Last month, Wikimedians from across the continent gathered in beautiful Edmonton, Alberta for WikiConference North America (WCNA) 2026—an opportunity to share projects, learn from one another, and think collectively about what it means to build and sustain the knowledge commons. For those of us working on the Wikimedia North America Hub, it was also a wonderful chance to meet so many community members in person and listen to the extraordinary work already happening across our region.

Throughout the conference, one theme surfaced repeatedly: representation is not simply a matter of adding more information. It requires attention to whose knowledge becomes visible, who gets to participate in creating it, and what structures shape that participation.

Stacy Allison-Cassin opened Saturday morning by asking how we can develop representation “that does not flatten,” invoking the principle “nothing about us without us.” Bisi Alimi, Executive Director of Wikimedia LGBT+, extended that conversation to language and linguistic colonization. He described the experience of native speakers having to place words from their own languages in italics—typographically marking them as foreign or somehow secondary to a dominant language. It was a small but powerful example of how the structures we use to organize and communicate knowledge can also encode relationships of power.

Ẹ ṣé púpọ̀, Bisi—thank you very much for that reminder. 🙂

Dominic Byrd-McDevitt reminded us that a historical record without provenance cannot be verified—and that a historical record without context is not neutral. Jamie Flood emphasized the urgency of mentoring young people as the next generation of thinkers, knowledge producers, and stewards, and of equipping them with the source-literacy skills they need to navigate an increasingly complex information environment.

Freddy Veloz shared how the Spanish-language LGBT Wikiproject made the enormous task of increasing representation manageable by identifying categories of missing knowledge and systematically addressing them. While names such as Oscar Wilde or James Baldwin may be widely known, every country—including places like Panama—has its own LGBTQ literary and cultural traditions worthy of documentation and visibility. So far, the Wikiproject has created an article on the LGBT history of each Latin American country, and is now expanding to more continents.

Jere Odell and Olivia MacIsaac’s work around notability raised equally important questions about how Wikipedia’s standards intersect with an uneven historical record: whose lives generated documentation, whose institutions preserved it, and whose histories therefore become easiest for our systems to recognize.

And Mark Graham offered a remarkable look at the work he and his colleagues at the Internet Archive do to preserve digital content that might otherwise disappear. One striking example was the preservation of more than 186,000 articles from BET.com—a significant record of contemporary Black American culture that could otherwise have been lost to digital obsolescence and erasure. It was a vivid reminder that preservation today is not only about protecting physical archives; increasingly, it means ensuring that born-digital cultural records survive at all.

The North America Hub at WikiConference North America

The HUB Mall at the University of Alberta

During WCNA 2026, the North America Hub had a presentation to introduce the work we do and a lunch session to foster discussion among North American Wikipedians about the successes and challenges they’ve had over the last year.

At the presentation, we introduced the Hub’s goal to help build an inclusive and sustainable regional Wikimedia ecosystem by strengthening collaboration across the region, supporting emerging and established Wikimedia communities, and making administrative resources, training, knowledge, and expertise more accessible. You can view the presentation slides here.

During the lunch session, the attendees chatted over lunch about their experiences in the last year. With participants from all over North America and beyond, it was inspiring to hear what has been going well and how the Hub can advise with outreach to potential partners, provide guidance with funding applications and grant reporting, and support multilingual communication. We also asked attendees to write down some of these experiences on Post-Its and place them on the wall for other people to see.

Some of the ideas shared during the lunch session


The Wikimedia North America Hub is inspired by all the great discussions that took place at WCNA and its work is grounded in Mary Louise Pratt’s concept of the contact zone and Élika Ortega’s application of that idea to digital humanities. This writer has been thinking of the Hub as a zona de contacto: infrastructure that enables communities with different languages, histories, resources, and ways of working to encounter and learn from one another without requiring those differences to disappear.

The Hub’s role is to build the connective tissue that allows many voices to participate, collaborate, learn from one another, and matter to one another. Edmonton was such a wonderful reminder that this work begins with relationships—and there is simply no substitute for being together in person, sharing meals and conversations, hearing about one another’s projects, and discovering connections we might never have found on a Zoom call.

We hope those conversations will continue well beyond the conference. Please join us for our next North America regional call on October 19 at 9 p.m. EST; the meeting link and details are available on our Meta-Wiki page. 

We also want to hear from you as we continue shaping the Hub. If you have not yet done so, please take a few minutes to complete our brief community survey. Your experiences, needs, ideas, and priorities should help determine what this regional infrastructure becomes.

If we are truly building the future of the commons, that work begins with listening—and with building it together.

Please be in touch!

Program Purpose

WikiConference India 2026 was the fourth edition of the national conference. It was held in Kochi, Kerala, from 4–6 September 2026 and hosted by the International Institute of Information Technology, Hyderabad, in collaboration with the Wikimedians of Kerala User Group. The conference brought together Wikimedians, developers, researchers, educators, community organisers and other contributors, with more than 220 participants from India and other countries. The conference was organised around the theme “Reimagining the Knowledge Commons: Community Leadership in an Evolving Wikimedia Ecosystem.”

Indic MediaWiki Developers User Group (IMDUG) works to provide technical support to Indic Wikimedia projects and communities through technical capacity-building activities. For the IMDUG, WCI 2026 provided an opportunity to engage directly with Wikimedia editor communities and better understand the technical challenges they face in their day-to-day workflows. 

The User Group approached WCI 2026 not only as a conference where members could present technical work, but also as an opportunity to strengthen collaboration between editors and developers. A major focus was to improve awareness and adoption of existing tools, identify technical challenges, support editors in navigating Wikimedia’s technical ecosystem, and identify potential areas for future technical development through collaboration with the community.

This approach was particularly relevant to IMDUG’s ongoing work in technical outreach and community engagement. The group’s Community Technical Task Force and earlier technical consultation activities were developed around the need to understand and document technical challenges faced by Indic communities and connect those needs with appropriate technical solutions, workshops, mentoring and future projects.

Planning and Design 

IMDUG planned its participation at WikiConference India 2026 around two complementary components: scheduled contributions to the conference programme and a dedicated technical engagement space. During the planning stage, the User Group developed proposals around technical tool adoption, community technical needs, IMDUG’s journey, and women’s participation and leadership in Wikimedia. Each activity was designed with a specific purpose, such as understanding community requirements, improving awareness of technical resources, documenting the User Group’s journey, or creating space for broader community discussion.

Alongside the scheduled programme, IMDUG developed a technical-space plan as a drop-in environment for direct interaction between editors and technical contributors. The proposed tables covered bug and feature-request reporting, learning to create Phabricator tickets, IMDUG activities and help-desk support, Community Technical Task Force discussions, extensions and MediaWiki core, tools, user scripts and gadgets, WikiLinkua project, and other community-led activities. The objective was to create multiple points of entry for participants depending on their technical needs and to connect community-reported issues with appropriate technical channels.

The conference was held from 4–6 September 2026, with the technical space planned primarily around the evening of Day 2 and the first half of Day 3. The design was intended to provide participants with different entry points for seeking technical guidance, discussing issues, learning about available resources, and exploring areas for collaboration. 

This planning approach aimed to ensure that IMDUG’s participation extended beyond session presentations by creating structured opportunities for community engagement, technical support, and the identification of follow-up actions.

Participation

IMDUG members participated actively in WCI 2026 through User Group-led activities, contributions to the wider conference programme, and volunteer roles supporting the organisation of the event. The User Group led four sessions and activities focused on technical tool adoption, community technical needs, IMDUG’s journey, and women’s participation and leadership in Wikimedia. IMDUG also proposed a dedicated technical space to facilitate direct interaction between editors and developers.

Beyond IMDUG-led activities, members also contributed to the wider conference programme. Navya Sri Kalli, an IMDUG member, participated as a panellist in the “Who Leads the Commons? Women in Wikimedia” panel. Her contribution brought an IMDUG perspective to broader discussions on women’s participation, leadership, and experiences across the Wikimedia movement.

Members also contributed to the wider organisation of WCI 2026 through volunteer roles. Gauri Gupta supported the communications team, while Harigovind C B contributed to the logistics team. These contributions complemented IMDUG’s formal programme and reflected the involvement of its members across different aspects of the conference.

In addition, IMDUG members participated in sessions covering AI and open knowledge, Indic-language technology, regional language communities, community development, governance, policy, funding and the future of the Knowledge Commons. Taken together, these forms of participation enabled IMDUG to engage with the conference at multiple levels, strengthen relationships across Wikimedia communities, and contribute both technical and organisational perspectives to the wider event.

The following sections provide a detailed overview of IMDUG-led and proposed activities at WCI 2026. They highlight the objectives, discussions and key outcomes of each activity, and illustrate how the User Group contributed to strengthening technical engagement, understanding community needs and supporting broader participation across the Wikimedia movement. 

Why Technical Tools Don’t Get Adopted?

The session explored why technically useful Wikimedia tools often remain underused, focusing on discoverability, usability, documentation and community-product fit, and highlighted the need to consider adoption from the early stages of tool development. A Tool Adoption Checklist was proposed as a practical output for future technical projects.

Identifying and Prioritizing Community Technical Needs

This interactive activity brought editors and developers together to identify workflow pain points, repetitive tasks and technical challenges faced by communities. It focused on understanding community needs before defining technical solutions and identifying issues that could be taken forward through appropriate technical channels such as Phabricator. The activity identified a prioritised list of community technical needs for future work.

Technical Space and Round-table Activities

IMDUG proposed a dedicated technical space to provide editors with direct access to developers for technical questions, bug reports, tool-related queries and workflow issues. The planned format included round tables covering Phabricator, tools, extensions, user scripts, gadgets, Community Technical Task Force discussions, and IMDUG activities.

Poster Presentation: Journey of the Indic MediaWiki Developers User Group

The poster presented IMDUG’s journey from its early beginnings to its development as a recognised Wikimedia affiliate. It highlighted the group’s work in technical development, mentorship, community support, events and capacity building, while also documenting lessons that other Wikimedia communities could adapt when building their own technical communities.

Panel Discussion: Women, Wikimedia and Technology: From Participation to Leadership

The panel brought together women contributors from different roles across the Wikimedia movement to discuss their journeys, mentorship experiences and pathways from participation to leadership. The discussion also explored the importance of supportive community environments and greater representation of women and diverse perspectives in Wikimedia.

Outputs and Outcomes

WCI 2026 resulted in several concrete outcomes for IMDUG, particularly in relation to the User Group’s visibility, community engagement, and identification of follow-up technical needs.

  • Improved visibility of IMDUG: The conference increased awareness of IMDUG among a wider section of the Wikimedia community. Members were approached by contributors with technical questions and were able to introduce the User Group’s work, activities and available technical support to communities that had not previously engaged closely with IMDUG.
  • Community-specific technical needs identified: Discussions with contributors from Telugu, Nepali, Punjabi, Gujarati, Sindhi, Tulu and Kannada communities highlighted a range of technical and workflow needs. These included continued technical engagement and demonstrations for the Telugu community; technical issues and a request related to opening a Phabricator workboard from the Nepali community; and Wikisource-related tool issues and limited awareness of technical support channels among Punjabi contributors. Conversations with Tulu and Kannada contributors also established contacts for continued technical engagement.
  • Follow-up opportunities identified: The discussions provided concrete areas for continued engagement through community calls, technical consultations, workshops, hackathons and Community Technical Task Force activities. These interactions also helped IMDUG identify where existing tools, documentation and technical guidance could better address community requirements rather than assuming that new development was always necessary.
  • Inputs for future technical activities: The needs and feedback gathered during the conference have informed areas where IMDUG can strengthen its existing programmes and develop new initiatives. This includes making technical resources and tools more editor-friendly, improving how existing workshops and support activities are delivered, and exploring initiatives that address gaps in communication and collaboration between editors and developers.

What Went Well

  • Focused Technical Engagement: IMDUG’s activities focused on technical tool adoption and understanding community technical needs, providing a basis for future engagement and follow-up initiatives.
  • Diverse and Meaningful Discussions: The conference enabled members to engage with developers, experienced technical contributors, language communities, organisers, and contributors working across governance, education, policy and community development.
  • Increased Visibility of Technical Contributions: The event helped showcase that technical contribution extends beyond software development to include documentation, testing, user scripts, gadgets, issue reporting, maintenance and mentoring.
  • Valuable Community Interactions and Follow-up: Informal conversations outside the formal sessions helped IMDUG better understand community-specific challenges, exchange ideas, build new connections, and identify opportunities for continued technical support and collaboration.

Key Learnings and Areas for Improvement

WCI 2026 highlighted several key learnings for IMDUG on how to identify, communicate, and translate community technical needs into effective technical support. A key takeaway was the importance of understanding the underlying community problem before deciding on a technical solution.

  • Start with the Community Problem: Not every technical challenge requires new tool development. Some needs may be better addressed through existing solutions, improved documentation, usability changes, or clearer technical guidance. Future technical work should therefore begin by understanding the problem and assessing available solutions.
  • Adoption as Part of Technical Work: A technically functional tool may remain underused if communities cannot easily discover, understand or integrate it into their workflows. Documentation, onboarding, usability, discoverability, and ongoing support should therefore be considered alongside development.
  • Stronger Editor–Developer Collaboration: Direct interaction between editors and developers helps translate real workflow challenges into clearer technical requirements. It also enables editors to better understand how to communicate their needs through appropriate technical channels.
  • Building Sustainable Community Capacity: Long-term technical impact requires communities to have the ability to find and use existing resources, report issues, provide feedback, and participate in shaping technical solutions. IMDUG can contribute by making technical support and participation more accessible to communities with different levels of technical experience.
  • Focus on Existing Tools and Resources: Participants highlighted challenges related to the discoverability, documentation, usability and accessibility of existing tools and technical resources, indicating areas where improvements could increase their usefulness and adoption. 

Future Plans

Based on the discussions and feedback received during WCI 2026, IMDUG plans to strengthen its focus on making existing technical resources more accessible, discoverable, and useful for Indic Wikimedia communities.

  • Improve Technical Documentation: Introduce a dedicated documentation track in IMDUG events to review and improve existing tool documentation from an editor’s perspective, with greater emphasis on screenshots, practical examples and clear, step-by-step instructions.
  • Support Localisation of Documentation: Involve editors participating in IMDUG events in translating and adapting technical documentation into their respective languages, helping make existing tools and resources more accessible to local communities.
  • Follow Up on Community-Reported Issues: Continue engagement with communities that raised technical challenges during WCI 2026 and support them in finding appropriate solutions.
  • Prioritise Community-Backed Technical Projects: Future technical events and workshops will focus more strongly on projects that emerge from documented community needs and have a realistic pathway toward adoption.
  • Focus on Long-Term Adoption: Move beyond developing tools alone by placing greater emphasis on documentation, user testing, community feedback, maintenance and continued support to ensure that technical solutions remain useful and sustainable.

Conclusion

WikiConference India 2026 gave IMDUG an opportunity to engage with a broad range of Wikimedia communities, strengthen connections with language communities and identify technical and workflow challenges faced by editors. The conference reinforced that effective technical contribution depends not only on development, but also on discoverability, documentation, usability, community engagement, and continued support. The connections and feedback received at WCI 2026 provide a basis for IMDUG’s follow-up work with Indic Wikimedia communities. 

Growing Active Technical Contributors in ESEAP

Friday, 16 October 2026 09:00 UTC

This article is a reflection on the author’s time in Wikimedia Indonesia from 2023-2026.

I joined Wikimedia Indonesia (WMID) in September 2023, during a transitional period. I was assigned to lead Wikidata programs in Indonesia, working with the Wikidata Indonesia Community. The learning curve was steep, but I was fascinated by how Wikidata describes real-world concepts, connects them, and the potential it holds.

Learning from the people who learn

WikiLatih Wikidata at BRIN (Affandy Murad, Wikilatih Wikidata BRIN 05032026 Affandy Murad Pelatihan, CC BY-SA 4.0)

Over time I met people from many backgrounds: academics, GLAM workers, activists, researchers working with data, students, and community members, and observed how they interacted with Wikidata. I saw a pattern: Wikidata is easier for people who already work with data, especially in computer-related fields.

So I began experimenting with teaching methods, drawing on learning theories I learned in high school at Gontor and my master’s at Universitas Indonesia. I tried behaviorist approaches, such as quizzes with rewards in workshops, and constructivist ones, designing activities within learners’ zone of proximal development. In community activities I saw a community of inquiry take shape, as teaching, social and cognitive presence emerged together. Under the guidance of two WMID chairs, I also established the annual Wikidata Research Grant, which for two years supported researchers working with Wikidata.

Each Wikidata workshop used slightly different materials, adapted to its audience. A slide deck for a general audience looked nothing like one for researchers at BRIN, Indonesia’s national research and innovation agency. I could never formalize a one-size-fits-all curriculum: the audience was too wide, and each group deserved to be treated as special.

In 2025, I was assigned to focus on data and technology collaborations and partnerships, and handed community-related work to a new staff member. I also oversaw the creation of the first Indonesian teaching material for Wikifunctions, compiled by an active functioneer from the community. It was well received.

Increasing Technical Contributions

WikiLatih session at UNHAS (Vyncensisio, Sarasehan Wikinusantara 10 April 2026 Universitas Hasanuddin 05, CC BY 4.0)

At WMID, I aspired to see more ESEAP community members, especially from Indonesia, participate in the Wikimedia Hackathon. I believed that technical contributions, such as collaborative development through Phabricator, module creation, templating and MediaWiki implementation, were seen as “out of reach” for all but a few. I wanted to push our community toward them, but the path is steep, and where does one even begin?

I brought this to a discussion session at the ESEAP Conference 2026 in Kaohsiung. Participants suggested many ideas, most starting with the learner: checking the baseline skill level (programming skills, etc.) before designing any training, and reusing existing online lectures. Others stressed investing in people through “train the trainer” programs, paid professional IT trainers, computer science students as a target group with incentives, and mentoring programs and monthly online meetings where “silly questions” are welcome. Surveying both tech and non-tech contributors would show which basics to introduce, and Capacity Exchange could help communities trade strengths and weaknesses. Looking outward, participants proposed beginner-friendly hackathons, technical conferences such as COSCUP, competitions, Wikidata showcases with other user groups, and building ties with open source communities.

The challenges were just as varied. Newcomers find it hard to choose the right QID and PID, and few contributors in some communities work on Wikidata. Hackathons may not be accessible to beginners, a one-hour workshop is not enough, and newcomers often do not know what to do next or how to ask for help. One tension ran through everything: how do we make technical events welcoming without scaring beginners? Our shared answer was to show skill levels openly. Read the full notes here.

In the end…

As June 2026 approached, another transition arrived, and my journey with WMID was drawn to an end. For me, it is simply another chapter. I am now an active community member, and my work continues: I keep working on Wikidata, encouraging others to reuse its content, and combining code and data through the Wikimedia API to build tools that help our editing. These are small steps toward closing the knowledge gaps in this ever-expanding movement.

This article is the second in a planned series of three. It was originally written for publication in May but was delayed due to unforeseen circumstances, and has since been updated and rewritten. As of July 2026, the author is no longer affiliated with Wikimedia Indonesia.

Manuel Vargas y Ramón Rocha Monroy junto a otros escritores en la Feria Internacional del Libro, 1997

A few months ago, a tribute was held for the writer Víctor Hugo Viscarra, who, in terms of European literature, could be called a “cursed poet.” Víctor Hugo was a writer who lived on the streets for long periods of his life and recounted anecdotes and stories from that life in his books. 
We came to know this writer in Bolivia thanks to fellow writer Manuel Vargas, who was his editor.

During his lifetime, Víctor Hugo Viscarra was not part of the literary canon, nor was he considered an “exportable” writer, but some bars and cultural venues still hold tributes to him. I happened to meet Manuel Vargas, Viscarra’s editor, at one of these venues and made initial contact to begin the work we would later carry out with the Bolivian Wikimedia team. To continue, it’s important to know that Manuel Vargas is a Bolivian writer and book activist. He has participated in numerous book fairs and alternative venues outside the official circuit. He studied literature at the Universidad Mayor de San Andrés in La Paz,  although he was born in Vallegrande. His works include notable children’s fiction, and he has participated in gatherings of children’s literature writers. He has also maintained connections with storytellers from eastern and southern Bolivia. Manuel Vargas has witnessed the development of Bolivian literature at a pivotal moment. 


He was a student and later a friend of the poet Pedro Shimose and hundreds of other writers who began their professional careers during the same period, the 1970s. Political ideals and the spirit of the times led to close relationships with various people who at one time or another worked in the arts in La Paz and Bolivia. These relationships were also strengthened by the migration resulting from the various coups d’état that took place in Bolivia from the 1960s through 1982. 

After coordinating with the team, I initially contacted him because a photograph was missing from his article. Manuel invited us to his home and told us about his photo archive, which contained valuable photos that had been stored in a family box, waiting for someone to bring them back into the spotlight. Opening his family home to the Wikimedians allowed us to conduct a joint review and identify a plan of action. The first step was to sort through and discuss the albums, their contents, the time periods they covered, and the people featured in them. We reviewed hundreds of images—some in color and others in black and white, some individual shots and others grouped by era or theme.

A large number of images had significant documentary value, so it was a challenge to select a priority group for the project. The images led us to engage in dialogue and explore both the family history of Manuel Vargas and the history of the artistic communities in our cities—images depicting travels and the participation of celebrated literary figures in book fairs, discussions, and gatherings. All these spheres were represented in both formal and informal settings, and many addressed topics that remain a gap in Bolivia’s online historiography.

In this process of sharing the faces of writers and cultural organizers, there is also a historical reconstruction of the spaces that were created to promote literature—such as the second edition of the International Book Fair in La Paz, writers’ gatherings in Santa Cruz and Cochabamba, as well as occasions when Bolivian literature found venues for dissemination beyond our national borders.

Illustrious names without faces.

Thanks to this work, we were able to begin reconstructing the careers of writers, artists, and cultural organizers from the 1970s to the early 2000s. After a review, we compiled a collection of 62 images that were donated by the family for publication under a free license on Wikimedia Commons. Part of this family archive can be viewed in the article on Vargas, as well as in the article on Pedro Shimose. The image in the article features Ramón Rocha Monroy, a renowned writer from Cochabamba. We also have photographs of him with his colleagues: Humberto Quino and Adolfo Cárdenas—a poet and a novelist, respectively—during a writers’ gathering held in the United States.

The archive includes a photograph of the Oruro-born poet Alberto Guerra Gutiérrez, of whom only a bust in his hometown had previously been known.
We also have photographs of Alba Paz Soldán, a writer and cultural manager. In addition, there is a photo of Manuel spending time with those who would later form the editorial team of Chaski, the iconic children’s magazine of the 1990s, which combined Bolivian mythology with a child-centered approach that encouraged children to participate in creating the content.

Among the photographs, we find Victor Hugo Viscarra hidden in a large crowd, alongside the painter Edgar Arandia. All those mentioned are distinguished figures in the Bolivian art world who, however, did not have images included in their respective articles. This collection also features figures who have played important roles in cultural management but who do not yet have articles dedicated to them.

Director del Centro Simón I. Patiño, Edgar Arandia, David Acebey, Victor Hugo Viscarra, Max Aruquipa en una presentación realizada en la Casa de la Cultura

Por otra parte, identificamos otra cualidad de las imágenes. Las mismas nos permiten ver el paso generacional que existe entre la literatura de posguerra en los años 40 y la literatura contemporánea. Las características temporales se hacen evidentes cuando se combinan las imágenes, los artículos y la curiosidad lectora. De esa forma, se puede reconocer el cambio de temáticas y personajes como signo del cambio en las sociedades por procesos marcados por la migración, la dictadura y el retorno a la democracia.

Los retos en este camino

We also identified another characteristic of the images. They allow us to see the generational shift between postwar literature of the 1940s and contemporary literature. The temporal characteristics become evident when the images, articles, and the reader’s curiosity are combined. In this way, one can recognize the shift in themes and characters as a sign of societal change driven by processes marked by migration, dictatorship, and the return to democracy.

There is still a great deal of work ahead in this historical reconstruction of our literature, beyond its quality and comprehensive approach. We also face Wikipedia’s notability guidelines, which in turn pose challenges for reconstructing literary trajectories in a medium where publication was complex and rare. The result is often that articles are deleted. This hinders the work of preserving memory, but our team views these steps, obstacles, and setbacks as part of the job.

We would like to conclude this text by acknowledging and thanking those who are so committed to preserving this history—the Vargas family, specifically Manuel Vargas and Vicenta Guzmán— whose collaboration on this project allows us to maintain an optimistic outlook as we continue the Family Treasures project and keep discovering these images that give a face to the words that have shaped  several generations of local readers—words that can now continue to speak to today’s youth with a familiar face and the warmth of a photo of an uncle or  a family friend willing to share their stories, insights, art, and love for Bolivia.

If you are a relative of—or know relatives of—people who have made history in Bolivia, and you have photographs or other materials you’d like to share, please contact the Wikimedians of Bolivia so that together we can explore the possibility of using Wikimedia Commons as the repository to make this material accessible to everyone.

Students bring Mayan hip-hop music to Wikipedia

Thursday, 15 October 2026 16:00 UTC

When you think of Mayan languages, hip-hop music may not be the first thing that comes to mind. The modern music genre wasn’t on Eve d’Evegnee’s radar either, until she and her classmate found it when searching for scholarly articles on Guatemalan art and music. 

Nearly 5,000 words and a new article later, they’re the editors who brought it to Wikipedia.

“Through this article, I hope that readers will gain a new appreciation for Mayan languages,” explained d’Evegnee, a junior majoring in History and Spanish.

Eve d'Evegnee
Eve d’Evegnee. Image courtesy Eve Eve d’Evegnee, all rights reserved.

Mayan languages, which have survived centuries of colonization and genocide, are spoken by over 6 million people throughout Mexico and Central America.

Across the Yucatán Peninsula, the highlands of Guatemala, and the state of Chiapas, artists have been recording hip-hop in Mayan languages, rapping about Indigenous identity, land, migration, and cultural survival. Some have drawn on ancient sacred texts like the Popul Vuh. Others have used their music to process the legacy of the Guatemalan genocide, or created hip-hop schools to offer young people an alternative to gang activity and violence.

The article was produced as part of d’Evegnee and her classmate’s Wikipedia assignment with history professor David-James Gonzales, who asked his students to use what they learned in the classroom to identify an understudied research area, gather credible source material, and publish a new Wikipedia article on the subject.

“I enjoy using the Wikipedia assignment as an alternative to research papers because it mimics some of the same pedagogical practices and learning outcomes while teaching students how to write in a neutral (un-biased tone), which I believe is more engaging and useful outside of academia,” said Gonzales. “Both my students and I appreciate that Wikipedia is a public educational resource they both benefit from and contribute to.”

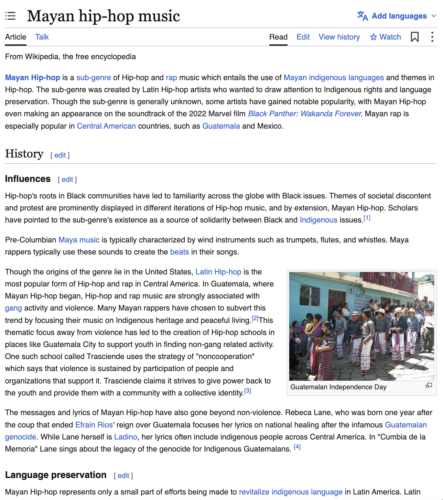
Screenshot of the Wikipedia article for Mayan hip-hop music.

Gonzales can anticipate what his students will learn from the project, but he’s always pleasantly surprised by the topics they choose to explore.

“My goal is for students to gain a deeper appreciation for people, places, and experiences that they had little to no knowledge of previously and this article on Mayan hip-hop music is an excellent example,” said Gonzales. “Neither [student] had any knowledge or exposure to the genre previously. They were drawn to the topic because it illustrated course themes, like the process of migration and acculturation.”

Supported by twenty-six references, the article is now part of public knowledge, available to other students, researchers, and curious readers. Readers will learn about the context for the regional variations of the genre, and discover the stories behind artists like Pat Boy, who has spent years running hip-hop workshops to keep Yucatec Maya alive among young people, or Balam Ajpu, who consult a Mayan priest before writing lyrics.

Now Wikipedia is one more place where people can discover them.


Interested in incorporating a Wikipedia Assignment into your course? Visit teach.wikiedu.org to learn more about the free resources, digital tools, and staff support that Wiki Education offers to postsecondary instructors in the United States and Canada. 

In May 2026, I travelled to Milan, Italy, for the Wikimedia Hackathon 2026. It was my first international trip, and an opportunity I had never imagined for myself. I arrived with a project idea, a few days to work on it, and no idea that I would leave with the beginnings of something I would continue building months later.

Looking back, Milan was not just about attending an international event. It was about discovering how a community of people with different backgrounds, skills, and interests can turn an idea into something others can use.

One project finished, another just beginning

I arrived in Milan planning to work on a Wikidata watchlist filtering script. The idea was to make reviewing edits more manageable by allowing users to filter their watchlist by categories. I completed the script on the first day.

With time left, I joined an unconference session by Satdeep Gill and Silvia Gutiérrez. Their discussion introduced me to WikiLinkua, a language-learning platform built around Wikidata Lexemes and Wiktionary.

The idea caught my attention: what if people could learn a new language using languages they already know, while also helping improve the free knowledge that makes this possible?

Language learning tools often focus on helping people consume content. WikiLinkua offered another possibility: helping learners discover gaps in open language data, such as missing pronunciations or meanings, and creating opportunities for them to contribute back.

I started building a prototype in Milan and presented an early version during the hackathon. It was only a beginning, but the project had found its direction.

Taking the project home

Returning to India did not mean leaving the project behind.

At the Indic Wikimedia Hackathon 2026 in Hyderabad, organised by the Indic MediaWiki Developers community, I continued working on WikiLinkua. This time, I also had the opportunity to mentor contributors working on the project.

Working alongside my mentee, Advait Dintakurti, we developed and deployed Version 0 on Toolforge. Seeing an idea that began as a prototype in Milan become an accessible web application was a rewarding milestone. Just as importantly, the process became an opportunity to collaborate, share what I had learned, and help someone else contribute to the project.

You can explore the current version at wikilinkua.toolforge.org or browse the code on GitHub.

There is still a great deal to do. WikiLinkua is an evolving project, and feedback, contributions, and ideas from the community will be essential to its growth.

A journey that began closer to home

My involvement with Wikimedia began in 2024, when I had the opportunity to volunteer at the Wikimedia Technology Summit. That experience introduced me to the people and communities behind the technical side of the Wikimedia movement.

Since then, I have contributed to Wikimedia-related tools, participated in hackathons, and learned from developers and community members who have been generous with their time and guidance. My journey has also been shaped by the support of the International Institute of Information Technology Hyderabad, which has been an important part of my academic life.

I am grateful to everyone who helped make these opportunities possible, including the Wikimedia Foundation for supporting my participation in Milan, the organisers and participants who welcomed me, and the Indic MediaWiki Developers community for providing a space to learn, contribute, and mentor others.

More than a prototype

For me, the most valuable part of this journey has been seeing how participation can grow into contribution, and how contribution can create opportunities for others.

I went to Milan intending to build a small technical tool. I returned with a new project, new collaborators, and a better understanding of what it means to build for an open knowledge movement. In Hyderabad, I had the chance to pass on some of what I had learned while working with another contributor.

WikiLinkua is still at an early stage, but I hope it can become more than a language-learning platform. I hope it can help connect language learners with the people, data, and communities working to make knowledge available in more languages.

If you are interested in language learning, Wikidata, or improving multilingual knowledge, I would love for you to try WikiLinkua and share your feedback.

The prototype is only the beginning. What happens next depends on what we build together.

What can Wikimedia education look like in different learning environments?

The September 2026 EduWiki Knowledge Showcase brought together experiences from Wikimedia communities in Central and Eastern Europe and Central Asia and Sub-Saharan Africa, giving participants an opportunity to hear how different education programmes are being developed and implemented in their communities. The session also included an update from the EduWiki Hub and a capstone project from the first cohort of the EduWiki Mentorship Program.

Learning through university internships

Mari Avetisyan of Wikimedia Armenia presented the organisation’s university internship programme, which gives students an opportunity to apply their academic knowledge and language skills through contributions to Wikimedia projects.

The internship runs for around two months. Students begin with Wikipedia training before creating articles, including translations from English, Russian, Chinese and Korean. Wikimedia Armenia currently works with three universities, and over eight years, 609 students have participated in the programme by contributing to Wikipedia.

Mari also discussed some of the challenges involved in sustaining the programme, including working with university administrations, maintaining the quality of contributions and keeping students engaged alongside their other responsibilities. The programme has helped students gain practical experience and confidence while strengthening Wikimedia Armenia’s relationships with universities.

Making the Starter Kit accessible

Rhoda James from the EduWiki Hub also introduced the hub’s Newcomers’ Starter Kit, a resource designed to help people get started with Wikimedia education activities. She gave an overview of how to find and use the Starter Kit, examples of the resource in Albanian and Spanish, and guidance on bringing the Starter Kit into other languages.

Inside EduWiki Camp 2026

Lora Milutinović from Wikimedia Serbia shared the experience of EduWiki Camp 2026. The four day programme brought together 17 participants, supported by two lecturers and three Wiki Ambassadors.

Participants explored Wikipedia, Wikimedia Commons, Wikidata and GLAM through a combination of learning activities, quizzes, debates, a museum tour and team building. The camp focused on developing critical thinking, evaluating and citing reliable sources, and writing in an objective encyclopedic style.

The programme resulted in 30 Wikipedia articles being edited, 17 new Wikipedia articles, 410 Wikidata entries and 321 images uploaded to Wikimedia Commons. The presentation also looked at how participants could remain engaged after the camp.

From mentorship to a working tool

The Showcase featured a capstone project from Dev Jadiya, a mentee from Cohort 1 of the EduWiki Mentorship Program.

Dev presented WhichTool, a multilingual, natural language search engine for Wikimedia Toolforge tools. The project demonstrates how mentorship can support participants in developing practical tools that address specific needs within the Wikimedia ecosystem.

Bringing Wikimedia into schools

Ayokanmi Oyeyemi from Wikimedia User Group Nigeria presented the Wiki in School Nigeria programme, which works with academic staff who become mentors for student cohorts.

The programme has developed through four years of learning and iteration, beginning with a pilot in 2023 and continuing through refinement and expansion. By 2026, the programme had trained 438 students, supported the creation and improvement of more than 1,200 articles, and reached 18 institutions across six communities.

One example came from Admiralty University of Nigeria, where a trained lecturer went on to guide students in Wikimedia activities. Twenty five students participated within one month, followed by the emergence of a school fan club with more than 30 active editors.

The presentation highlighted the importance of working closely with educators, giving students room to contribute to knowledge, and providing continued support after initial training.

A closer look at Wikimedia education work

Across the presentations, participants saw different ways that Wikimedia programmes can connect with formal education. The September Showcase created space for communities to share their experiences and for participants to ask questions during the discussion that followed the presentations.

The session was held with live interpretation in French and Portuguese, helping make the Showcase accessible to a wider audience.

The September edition brought together practical experiences from university programmes, school based initiatives, community learning and mentorship. These examples offer a useful record of how Wikimedia education work continues to develop across different contexts.

The session concluded with an EduWiki Hub update highlighting upcoming events where the Hub will be participating. Participants who will be attending the Wikimedia CEE Meeting or the Language Diversity Conference were encouraged to join the Hub’s sessions at these events. Showcase participants were also invited to register for the October EduWiki Workshop, which will focus on the Universal Code of Conduct.

The recording and additional resources are available on the Showcase’s Resources page on Meta-Wiki.

Get involved!

The EduWiki Hub invites you to be part of its initiatives:

Watch the recordings of the showcase here: Portuguese, French, and English.

For collaboration or questions, contact eduwikiug@gmail.com

LDC Ghana 2026 official logo

Last week in Accra, I had the opportunity of being part of the maiden edition of the Language Diversity Conference held in Ghana, with the theme “Strengthening Language Communities in the Open Knowledge Movement”. I was one of the self-funded scholars, which Dagbani Wikimedians User Group funded to boost much participation in this conference.  The conference brought together over 82 language speakers and over 120 participants for a period of three days. It was hosted by the Dagbani Wikimedia User Group, Wikimedia UK, the Wikimedia Language Diversity Hub and Wikitongues.

This conference matters to all of us because digitalizing our languages goes a long way toward preserving them, and with them our pride. We have a lot of Dagaare speakers, and it would be unfortunate if we were unable to document our language. As Professor Samuel Alhassan Issah, Dean of the Faculty of Ghanaian Languages Education at the University of Education, Winneba, put it, “A language becomes minoritized because society makes it so, and even a language spoken by millions can be pushed to the margins.”

Throughout the conference, experienced speakers from all over the world shared their knowledge and experiences. Mr Edmond Moukala spoke about UNESCO’s work on building an inclusive digital future through multilingualism, while Christian Ato Yakubu presented on Unlocking the Voice: Advocacy for Indigenous Language Digitization. Musah Fuseini introduced Sopala, a project supporting offline education through MoodleBox for the Dagbani language in the Northern Region, and Benjamin Ginsberg discussed the pros and cons of social media in a diaspora language, drawing lessons from a Ladino cooking show. These, and many more valuable presentations, were delivered over the three days.

Prof. Samuel Alhassan Issah

We did not just listen, write and ask questions orally; we also tried our hands at practical activities. The first was creating lexemes for Dagaare on Wikidata. For example, we entered the lemma “bibile” (child), selected Dagaare as the language and noun as the lexical category, added the forms bie, biiri and bibiiri, and finished with the sense “child”. We also had the opportunity to record our own voices in our various languages, upload the recordings to Wikimedia Commons and link them to Wikidata. In addition, we added labels in our various languages.

Beyond the sessions, participants were treated to some of Ghana’s amazing tourist sites, including Osu Castle, the Black Star Square and the Kwame Nkrumah Memorial Park.

Participants from different countries at the Kwame Nkrumah Museum

It was truly a wonderful experience, and I congratulate the organizing team on such a wonderful event.

I really appreciated the effort of the Dagbani Wikimedians User Group by giving me this opportunity, making a dream comes true.

Photographing the 50th ALP National Conference

Monday, 12 October 2026 12:00 UTC


Pangalau documents a conference for Wikipedia
, [Pangalau].

A note about the author - Pangalau is a Bruneian freelance photographer, member of Wikimedia Australia and Wikipedia editor based in Adelaide.

Jim Chalmers and me!

In July 2026 I attended the 50th Australian Labor Party National Conference, held from 23 to 25 July at the Adelaide Convention Centre. I was there as a contributor representing Wikipedia, Wikimedia Australia and Wikimedia Commons, documenting the event through photography and releasing the images under a public domain licence.

I've never been affiliated with a political party, so this was a chance to observe Australian political processes closely. Over the three days, delegates debated the Albanese government's priorities and the party's policy direction, including cost-of-living measures, gender-based violence prevention, and a pathway to universal dental care under Medicare.

I attended a press interview with former minister Ed Husic, following a debate over a motion on the party's position on Israel. I also photographed Prime Minister Anthony Albanese at the launch of the updated edition of The Light on the Hill.

On a more personal note, it was a pleasure to meet Robert Tickner, Australia's longest-serving Indigenous Affairs minister, who attended on behalf of the Justice Reform Initiative to advocate for criminal justice reform. I also met (and photographed) Michelle Ananda-Rajah, Jim Chalmers, Renee Coffey, Mira El Dannawi, Peter Greste, Christopher Pyne, Margaret Reynolds, Wayne Swan, and Erin Thompson, along with many others throughout the conference.

I'm grateful for the new connections I made over the three days, including the chance to show some new friends around Adelaide.

My photographs from the conference are now on Wikimedia Commons, released into the public domain. Some have already been picked up by news outlets, including the Byron Shire Echo.

Thank you to everyone I met at the conference, and to everyone who has used the photographs since.

This Month in GLAM: September 2026

Sunday, 11 October 2026 23:00 UTC

weeklyOSM 846

Sunday, 11 October 2026 00:00 UTC
weeklyOSM 846
[1] | Wikimedia Enterprise team writes how CoMaps downloads Wikipedia articles to link them to OpenStreetMap data | Photo by Anton from CoMaps, CC BY 4.0 | Map data © by OpenStreetMap Contributors.

01/10/2026-07/10/2026

Mapping

  • Mateusz Konieczny proposed a mechanical edit that would move info about material from bollard= to material=. It would include editing bollard=concrete/wood/stone/rock/metal/plastic.

  • Mappers in the United Kingdom are considering removing the brand:wikipedia tag, which was mostly set from presets from the name suggestion index that no longer include them, two years after the same thing was done in the United States.

Mapping campaigns

  • Ballerup Municipality thanked OpenStreetMap Denmark volunteers for a successful September 2026 mapping campaign that significantly increased the mapping of accessible parking spaces.

Community

  • While you are enjoying the #31DayOSMChallenge don’t forget that the #30DayMapChallenge will soon be here. This year’s list of themes has been published.

  • Aselnigu explained how new data gets onto the OpenStreetMap.de map.

  • Rawaz explained how Claude AI can help map complex 3D buildings in OpenStreetMap.

OpenStreetMap Foundation

  • The OpenStreetMap Foundation Local Chapters and Communities Working Group launched the 2026 Community Microgrants, offering a total of EUR 5000 that will be distributed to various OpenStreetMap communities in grants of up to EUR 500. Applications are open from 5 to 25 October for small, concrete, and time-bounded activities that support mapping, data improvement, knowledge sharing, or community growth.

Events

  • OSM ENSTP (École Nationale Supérieure des Travaux Publics, Cameroon) organised ► a practical workshop on bridging paper and digital data for local urban planning on 4 October 2026. In collaboration with HeiGIT, the UN Mappers and GeoWakanda, the club brought participants together on campus to explore participatory mapping.

  • The FOSSGIS programme committee announced ► that the next FOSSGIS conference will take place in Heidelberg (Germany) from 9 to 13 March 2027.

  • The State of the Map Latam 2026 will take place from 27 to 29 October at the Antiguo Colegio de San Ildefonso in Mexico City. Those who wish to attend in person can register now.

Education

  • Hans van der Kwast gave a workshop, ‘Hydrological Analysis in QGIS’, at the QGIS User Conference in Laax, Switzerland. They explored the new native QGIS 4.4 tools for flow direction visualisation, stream extraction and catchment delineation, and a diverse range of tools for conducting comprehensive hydrological analysis. Materials are available at @gisocw.

Maps

  • nicofr77 has developed Tisseur de Voies, a website that calculates bike loops with a return journey by train. The cycle routes come from OpenStreetMap and the national cycle-route database (France), while the basemap comes from OpenStreetMap. Journey times come from open-data timetables published by SNCF, Île-de-France Mobilités, the Provence-Alpes-Côte d’Azur region, and the Corsican Railways.

  • Yury Kosharovskiy has created Star Ninja, a free web map for planning a night of stargazing. It shows sky darkness, cloud forecasts, and moon visibility for any spot on Earth, using OpenStreetMap data through Nominatim (place search) and MapLibre GL JS with OpenFreeMap tiles.

OSM in action

  • Home Assistant 2026.10 has introduced a redesigned map built on the OpenStreetMap Foundation’s vector tile service, marking a significant milestone for its adoption by major open-source projects. The new maps features smoother rendering, dark-mode styling, improved markers, and clustering. Home Assistant proxies and caches tiles locally, reducing the load on OSMF infrastructure. The release credits Guillaume Rischard for initiating and leading the OSMF vector tile project, Paul Norman for developing the tile infrastructure, and the MapLibre, Shortbread, and VersaTiles communities.

  • Sebastian Mietzner has made KAIJUMIETZ, a browser game that builds any neighbourhood on Earth from OSM data and lets a giant cat destroy it in two minutes.

  • VivaMap, a free quality-of-life map built partly on OpenStreetMap data, now also covers the Netherlands. Four of its nine Swiss dimensions (schools, restaurants and nightlife, healthcare, and part of nature) are computed from OSM points of interest and building footprints, weighted by type and distance on an H3 hexagon grid. The aggregate scores are published as CSV under CC BY-SA 4.0.

Software

  • Stadia Maps shows how to build a custom map style in about 30 minutes by forking a MapLibre style, recoloring it in Maputnik, and hosting the JSON yourself, including authentication setup and common styling problems.

  • Stadia Maps has rebuilt its boundary processing pipeline so that each boundary retains the same disputed status at every zoom level, resulting in smaller tiles.

  • Heikki Kalliokoski has developed copilot.travel, a free web planner for road trips in Europe powered by OpenStreetMap data. It routes drives with self-hosted Valhalla and describes sights using linked Wikipedia/Wikidata entries or their OSM tags.

  • After two years of development Alexandr Lovkov has shared his web app RouteCycle, for creating convenient and engaging cycling routes. The app supports displaying landmark photos from Wikimedia Commons and Strava integration for tracking unexplored roads and landmarks.

  • The Wikimedia Enterprise team published an article about how CoMaps downloads Wikipedia articles to link them to OpenStreetMap data to provide offline access.

  • Erick de Oliveira is bringing back the OSM Smart Menu as an open-source extension for Chrome and Firefox. With a single click, it opens your current location at the same zoom level on other maps, in mapping tools such as iD, JOSM, or OSMCha, and also in Wikipedia articles containing coordinates without the need to enter any data.

  • Rua de Cima is a free tool for house hunters in mainland Portugal. It uses official statistics to compare ► a home’s asking price with nearby sale prices and shows walking and driving times to schools, health care, public transport, shops, and beaches. Place and road data come from OpenStreetMap, routes are calculated using Valhalla, and the basemap uses Protomaps.

Releases

  • GraphHopper has released version 11.1, fixing a remote code execution issue.

  • Nearly two months since the last report, we received a new recap of changes to openstreetmap.org. Some of these include a new version of iD (with updated tagging schema), tweaks to notes, and a new effort to track and help fix errors that were invisible to the team. But the spotlight is on the changes to visibility settings for uploaded GPX traces. These were announced back in May (we reported earlier), and have now landed for the general public, including a page that mappers can use to update their past traces in bulk in order to bring them up to the new spec.

  • HeiGIT announced a major release of openrouteservice with version 10.0.0, also known as Amalthea. This release focused mostly on the technical foundation of the engine. It upgraded Java and Spring Boot, reduced the set of release artefacts to a fat jar and Docker images, and moved the slim Docker image to a hardened distroless base.

  • Organic Maps released its September 2026 update with route optimisation, improved alternative routes, individual track hiding, and intermittent water area rendering.

Did you know that …

  • … the Earth is getting rounder?

  • … you can easily edit OSM public transport relations using OSM Relatify?

Other “geo” things

  • Heise reported that the European Space Agency determined a position using Galileo’s future Signal Authentication Service for the first time under real-world conditions. The technology is intended to make various types of GNSS spoofing attacks detectable.

  • The Nigeria Postal Service has launched its National Digital Alphanumeric Postcode, a precise, GIS-located address system for every building in Nigeria. To mark the launch, OpenCage shared several geo-trivia facts about Nigeria.

  • Sentient Media has published an interactive map of Iowa’s concentrated animal feeding operations that shows nearly 11,000 facilities, 126.4 million animals, estimated manure volumes, and violations since 2003. It uses data from the Iowa Department of Natural Resources alongside Sentient Media’s own estimates; the data and code are available on GitHub.

Upcoming Events

Country Where Venue What When
🇨🇭 Bern SBB Headquarter Open Transport Community Conference 2026 2026-10-06 - 2026-10-09
🇬🇭 Ghana Everywhere She Maps workshop 2026 2026-10-07 - 2026-10-08
🇹🇭 กรุงเทพมหานคร Brighton College Bangkok Mapathon Missing Maps Mapathon (Beginner) - Bangkok, Thailand 2026-10-08
🇹🇭 กรุงเทพมหานคร Chulalongkorn University Fund Geo Class Mapathon, Survey Engineering Chula 2026-10-08
🇧🇪 Bruxelles - Brussel Galerie Bortier Brussels meetup - byebye Thierry & Joost 2026-10-08
🇩🇪 Bochum Das Labor, Alleestraße 50, Bochum OSM-Treffen Bochum 2026-10-08
🇩🇪 Berlin Grosse Hamburger Strasse 37, 10115 Berlin 220. OSM-Stammtisch Berlin-Brandenburg 2026-10-09
🇨🇭 Bern Restaurant Kairo OSM-Znacht in Bern 2026-10-09
🇮🇹 Catania Biblioteche Riunite Civica e A. Ursino Recupero Modifichiamo Wiki e OSM insieme! - Catania 2026-10-10
🇹🇭 กรุงเทพมหานคร Public House Hotel Bangkok OSM Thailand Community & HOT Meet-up 2026-10-10
🇫🇷 Angers École Nationale Supérieure d’Arts et Métiers OpenStreetMap, des cartes à la carte ! 2026-10-10
🇭🇺 Salgótarján Salgótarján - völgyváros gyár Salgótarján Mapping Party 2026-10-11 2026-10-11
🇩🇰 København Cafe Bevar’s OSMmapperCPH 2026-10-11
🇫🇷 Angers École Nationale Supérieure d’Arts et Métiers OpenStreetMap, des cartes à la carte ! 2026-10-11
🇧🇪 Espace Public Numérique (EPN) de Neufchâteau OpenStreetMap 2026-10-12
Panoramax Nederland - Online Community Meeting #1 2026-10-12
CartONG : Mapathons en ligne 2026-2027 2026-10-12
🇳🇱 Amsterdam TomTom HQ 2026 Autumn Maptime 2026-10-12
🇩🇪 München Echardinger Einkehr Münchner OSM-Treffen 2026-10-13
🇩🇪 Hamburg Voraussichtlich: “Variable”, Karolinenstraße 23 Hamburger Mappertreffen 2026-10-13
🇩🇪 temporärhaus OSM-Stammtisch Ulm/Neu-Ulm 2026-10-13
🇬🇧 Canolfan Cefnfaes 🏴󠁧󠁢󠁷󠁬󠁳󠁿 North Wales Mapathon Gogledd Cymru 🏴󠁧󠁢󠁷󠁬󠁳󠁿 2026-10-14
🇪🇸 Barcelona Barcelona Assemblea d’OpenStreetMap Català 2026-10-14
🇧🇪 Bruxelles - Brussel Tour & Taxis, Avenue du Port 86C - 1000 Brussels FOSS4G Belgium 2026-10-15
OSMF Engineering Working Group meeting 2026-10-16
🇩🇪 Potsdam 11-line Potsdamer Mappertreffen 2026-10-16
🇦🇷 Pergamino Hub de Innovación Encuentro OSM Argentina 2026 2026-10-17
🇫🇷 Metz Espace Arob@se - Metz Atelier OpenStreetMap Metz 2026-10-17
🇮🇳 Noida Noida OSM Delhi NCR Mapping Party No.33 (Noida) 2026-10-18
Missing Maps London Mid-Month for Advanced Mappers (no training provided) (Online) [eng] 2026-10-20
🇫🇷 Lyon Tubà Réunion du groupe local de Lyon 2026-10-20
🇩🇪 Chemnitz Kaffeesatz, Chemnitz OSM-Stammtisch Chemnitz 2026-10-20
🇩🇪 Bonn Dotty’s 205. OSM-Stammtisch Bonn 2026-10-20
🇬🇧 City of Edinburgh Guildford Arms Edinburgh Social 2026-10-20 - 2026-10-26
🇩🇪 Online Lüneburger Mappertreffen (online) 2026-10-20
Formazione Wikimedia Italia - OpenStreetMap: modifica tramite sito e tramite app 2026-10-21
🇩🇪 Karlsruhe Schwarzer Kater Stammtisch Karlsruhe 2026-10-21
OSM US Mappy Hour: Mapping Accessible Trails 2026-10-21
🇩🇪 Berlin Online EarthPV: Mapping Photovoltaics 2026-10-22
🇩🇪 Berlin Wikimedia e.V. Tempelhofer Ufer 23-24,10963 Berlin OSM Hackweekend Berlin-Brandenburg 10/2026 2026-10-24 - 2026-10-25
🇸🇪 Uppsala Datorföreningen Update Mapping meetup in Uppsala 2026-10-25
CartONG : Mapathons en ligne 2026-2027 2026-10-26
Formazione Wikimedia Italia - OpenStreetMap: tasking manager 2026-10-26
🇩🇪 Heidelberg DEZERNAT#16 Rhein-Neckar OSM Treffen 2026-10-26
🇩🇪 Stadtgebiet Bremen Online und im Hackerspace Bremen Bremer Mappertreffen 2026-10-26

This weeklyOSM was produced by MatthiasMatthias, PierZen, Rob Yoegel, Strubbl, Andrew Davidson, barefootstache, derFred.
We welcome link suggestions for the next issue via this form and look forward to your contributions.

AI is a tool. The question is how to use it.

Saturday, 10 October 2026 06:04 UTC
The sentiment among Wikimedians is clear; there is no room for artificial intelligence.

In my opinion that is stupid. You do not blame the hammer; the problem is where the hammer lands. The point of AI is in its analytics. It is not necessary to ask for new information. It can be asked to analyse existing texts, for instance all the Wikipedia articles on the same subject. The objective would be to find inconsistencies and with a corpus as large as the "sum of all knowledge" there will be plenty.

Once we are made aware of inconsistencies, the implicit challenge we always faced becomes explicit. Important is that all the knowledge necessary is in the "sum of all knowledge" itself meaning that the AI can be trained on all content from all Wikimedia projects. This would make it a multilingual and multicultural model,

What one Wikipedia knows and another does not is an inconsistency and at first the least interesting one. More relevant is to know what one Wikipedia knows different from another Wikipedia. Things like is he alive or is she the minister of defence for Whereeverland. The difference is in references. 

When an AI points to inconsistencies and to the latest references, how can any self respecting Wikimedian object to a tool like this?

Thanks,

        GerardM

We in the Test Platform team have been working on speeding up the MediaWiki CI time for core with help from @hashar. In this post I'm gonna go through some of the things we did to speed up the browser tests in the first part of 2026. Spoiler: The median feedback time for the gated extensions job in the test pipeline went from almost 24 minutes in February to under 10 minutes in May.

First where we were: In February 2026 the gated extensions job (the job that tests multiple extensions against a change in core named quibble-with-gated-extensions-selenium-php83) took 23:54 to run in median. That means that you as a developer needed to wait almost 24 minutes before you get feedback on your patch and a reviewer could merge it. That was the median so 50% of the time, you needed to wait even more.

What is a realistic goal for feedback time? Is it 20 minutes? 10? Or maybe 1 minute? We settled on 10 minutes median as the goal, not knowing if it would be realistic or not. With that goal we also needed to tweak a couple of other jobs but today I'm going to focus on what we did with the browser tests. You can follow all the work we did in T420590.

Where to start?

The first thing to do was to make sure we measured it correctly. We had individual test run time in Jenkins and it turned out that @thcipriani created a system that gets metrics from Jenkins and stores them in a database. We used that raw data to create SQL queries so we could follow up data per month. Over time we created a dashboard for the data that we continue to use when we try to make the CI feedback faster: https://releng-data.wmcloud.org/-/dashboards/core

Once we had a way to measure and see improvements (and regressions) we could move on with the next step. Where should we focus and where should we make the changes? To do that we used perf stat to measure changes on a bare metal server (to avoid the noisy neighbor effect). That way we could run the current code, make adjustments (configuration changes etc) and reliably measure what a change will give us and CPU savings. We did tests with 50 runs, changed the configuration and measured again. We measured before and after every change. We did a lot testing and small implementations before we started, making sure we could turn on/off differently functionality in our setup.

The plan

The plan was to move out the largest extensions that took the most time to their own jobs and then minimize the CPU used by our tests and then use that CPU time to run multiple tests in parallel. First we win back a lot of CPU, and then we use it to run tests in parallel to make the feedback time shorter. By making the tests less CPU intensive and spreading out the work on multiple CPUs we make the test time scale in a better way. That was the plan.

Moving out the slowed extensions

We did the move of two extension to their own jobs at the same time that we did the other work. This work was already started by @hashar. @hashar and @zeljkofilipin moved out the two slowest extensions (WikiBase and GrowthExperiments). That saved us 6 + 3 minutes in two goes, so that was a great win. Almost 9 minutes win by just moving the slowest projects to their own jobs. The new jobs finish within our ten minute target so they will not contribute to the feedback time.

Next the improvements. We make them in the npm package that lives in core, so that when all changes are done, we can propagate those to the rest of the extensions that also use webdriverIO. Let's start.

Stop recording what nobody watches

With our measurements we could see that FFMPEG added a lot of overhead. We know that we want to be able to record videos but it's wasteful to do it all the time. First we configured FFMPEG for speed and low CPU usage (following best practices I've implemented in Browsertime to minimize the CPU usage and impact on the server). That made the videos larger in size and then we could compensate for that by decreasing the quality of the video. That work was done in T408328 and on our test machine that change saved 25% in CPU time and made the performance 10% faster.

We then added a switch (T410594) so you can turn on/off recording and it is off by default. That way when we have a problem in CI, we can enable that. As a last thing, we now only take screenshots on failure. Even though taking a screenshot does not add the same overhead as recording the screen as video, every small thing counts.

Make the browser cheaper

In our setup we didn't follow Chrome best practices for browser tests. Google has some recommendations of things to turn off to make the browser better suited for automation. We followed that and used some other best practices in T403357. That made some small improvement in CPU usage and hopefully more stability for the browser.

Once we stopped recording videos by default we could switch to use Chrome's built-in headless mode. Before we used XVFB as a virtual frame buffer where the screen is painted. Using built in headless is the fastest way to use the browser. In T409392 we measured that using headless made us save 12% in CPU time and made the tests 8% faster (and that was after the improvements we made with FFMPEG recording).

We also did some work to tune the screen size (we could measure the effect using XVFB) but using headless there was no difference so we didn't end up doing that change (T408325).

Spend the saved CPU on parallelism

We have freed up CPU time with the changes, let's reuse that CPU again by running tests in parallel. WebdriverIO has built in support that makes it easy. We tried different settings and ended up setting it by checking how many cores the machine has. We use 75% of available cores. We took 75% because the rest of the cores are needed for database/MediaWiki.

Then it also depends on how many spec files we have. WebdriverIO parallelizes per spec file, so creating smaller test files makes it easier to run more tests in parallel. To make core faster we split some long spec files into multiple files. On top of some other tweaks we could see that the run time for the actual tests went from 128-160 seconds to 48 seconds by running things in parallel for the core tests.

Ship it to everyone with wdio-mediawiki 6.3.0

When we finished the npm package that included all the speedups we've done, we upgraded all extensions that use it. That way every extension also gets the win we did for core and the gated extensions job becomes faster. The next step was trim and tune individual tests for the extensions that run in the gated extensions job. One thing that helped was timing every command in the test suites. I had an LLM write the instrumentation, which logged how long each webdriverIO command took in CI. Then I looked at the slowest commands and tuned those tests.

Run the slowest tests first

One thing we noticed early when we started to run tests in parallel, was that we should optimize the order we run them: The slow test suites define the feedback time, start with some of the slowest suites first so that other threads can work on the short test suites and finish faster. We defined the order for the slowest test in the wdio configuration file. For core we could move the actual test time from 48 seconds to 25-30 seconds by just changing the order of the tests.

Small patterns with a big cost

There was a pattern in a couple of tests where we test if an element does not exist on a page using not.toExist.

In the version of expect-webdriverio (5.6.3) that we used, it didn't check once and returned. It kept polling until the element appeared or the timeout was reached. So if we had a timeout of 10 seconds, we tested that the element does not exist at all for the next ten seconds. However what we wanted to test was that the element wasn't on the page when we reached that code. The problem is that it wasn't obvious when you wrote the code that it would wait for the max timeout time until it returned.

The actual code fix at one place looked like this:

- await expect( EditPage.save ).not.toExist();
+ expect( await EditPage.save.isExisting() ).toBe( false );

The fixes were done in T419803. In one case we had two of those checks with a timeout set to 10 seconds each, so by fixing it we decreased the runtime from 21.2 s to 1.3 s.

This was later fixed in webdriverIO (expect-webdriverio 5.7.0) but at the time, I thought it was more of a feature and not a bug.

The final result

The median went from almost 24 minutes in February to under 10 minutes in May. Nine of the minutes came from moving out the slowest extensions to their own jobs. The remaining 5 minutes came from making the actual test setup faster.

What's the next step?

Once the browser test feedback was under 10 minutes and we fixed the other slow jobs, we kept on going. Our focus is making the gated pipeline (that runs after you +2 a change) faster and the goal is to have the p75 (75% of the time) to be faster than 10 minutes. We hope to finish that work sometime in October or November.

Every autumn, Wikimedia Europe brings together a group of Wikimedians who care about policy — volunteer advocates, staff, and people from like-minded organisations. Last week we held the eleventh edition of what we have always called, half-jokingly, the Big Fat Brussels Meeting. Thirty-one people from eighteen countries. Two days. Here’s a quick recap.

Day one: the state of the EU, and a sentence that stuck

The first day was devoted to the current EU policy situation: the EU Kids Act and age verification, AI and copyright reform, the CSAM Regulation, open government data, and what is happening with the Digital Omnibus. Affiliates shared updates from their own countries, which is always useful — EU decision-making is a constant back-and-forth between Brussels and national capitals, and having advocates who can carry consistent narratives and asks in as many places as possible is a structural advantage the Wikimedia movement is actively leaning into. For the first time, advocacy staff from Wikimedia Czech Republic joined the meeting. They asked for and received input from peers to help shape the chapter’s first comprehensive advocacy strategy. A staff member from Wikimedia in Ireland also attended — that team is just beginning to build its policy reflex, and it was great to see them attend.

A standout moment came from Signe Krantz of Wikimedia Sweden, who attempted to distil the movement’s core advocacy proposition into a single line — and, by the room’s reaction, largely succeeded: “Most people feel like they have a choice between the government or large corporations controlling their digital world. We have a third way for them.”

The framing of community-governed and not-for-profit platforms as an alternative to both state control and commercial capture struck a cord.

Day two, morning: how to hack AI?

The second day opened with a deep dive into AI. The goal was not to produce a position paper but to map the full range of AI-related work and ideas already happening across the Wikimedia movement, and to identify what Wikimedia Europe and its members might want to actively prioritise. The picture that emerged is, unsurprisingly, complex.

Wikimedia has a multifaceted relationship with AI. Our projects are used to train large language models and to ground their generative output. People and organisations with the movement develop tools. For instance an AI-driven citation tool already showing real promise, with potential reach well beyond Wikimedia projects with further investment. We grapple with what it means to keep our projects open while also working out how to ensure that large commercial AI systems contribute to the infrastructure costs they burden us with. And we need to defend against AI being weaponised for disinformation. We are also very committed to projects and communities that are human. After all, knowledge is human!

The group seemed to agree that AI needs human knowledge to have a chance to be trustworthy and grounded. Knowledge that is community-verified, openly licensed, maintained by people who care.

Aligning all of this into a coherent external narrative and concrete actions is challenging. But it is necessary, and this meeting was a step toward it.

Day two, afternoon: sharpening the message

The afternoon was given over to a communications workshop with an external specialist, focused on one core conviction: that community-governed platforms like Wikipedia are a booster for information integrity. Wikimedia is about human knowledge. As AI-generated content becomes ubiquitous, being able to defend and explain why that distinction matters, and why it is more important than ever, is becoming central to our advocacy work.

Partners and allies

The meeting also brought together a number of friendly organisations whose work intersects with ours in important ways. The OpenStreetMap Foundation attended — they are in the process of relocating to Brussels and exploring collaboration with Wikimedia Enterprise. IFLA, the international federation of library associations, was represented too. We worked on aligning positions across AI, child rights, copyright, and the treatment of the commons and cultural heritage. Commons projects and cultural heritage institutions share many challenges and goals. We can help each other, and amplify each other’s messages to lawmakers.

We will be back next year. In the meantime, the work continues.

A look inside the per-language scores of the MTEB leaderboard, with Indic languages as the test case.

Deepfakes are understood as realistic images, audio and video of real people that are generated or manipulated with AI. They can be used for parody, satire or to express valid social criticism. But they can be harmful in the cases of fraud, economic damages, disinformation and non-consensual intimate imagery.

Lawmakers in several EU countries (Belgium, Denmark and Cyprus) are trying to answer with new rights over a person’s likeness and voice, usually placed in copyright or neighbouring-rights law.

For the Wikimedia projects, which host and reuse media under free licences and also document public events and debates (including deepfake incidents themselves), the details of these laws matter. So let’s take a closer look!

Belgium: a new neighbouring right over image and voice

In September 2026 the Belgian Federal Chamber published a bill amending the Code of Economic Law with regard to deepfakes. It would insert a new Article creating a neighbouring right.

What it does

  • Every natural person gets an inalienable moral right over their image and voice, plus an exclusive right to authorise or prohibit the making, reproduction, distribution and communication to the public of a deepfake that uses them.
  • A deepfake is defined as AI-generated or AI-manipulated image, video or audio that resembles an existing or deceased person so closely that it may wrongly be taken for authentic.
  • The rights last 50 years after death and are then exercised by heirs. They can be licensed against appropriate remuneration, and collective management organisations can manage them.
  • Courts can order urgent provisional measures, including seizure and the blocking of accounts or domains, and can order removal and de-listing from search results. Online intermediaries must carry out such court orders without delay, “without prejudice” to the Digital Services Act (DSA).

The exceptions. There is no infringement where the person has consented, or where the deepfake is used for parody, satire or social criticism, provided a fair balance is struck with freedom of expression and the use does not disproportionately harm the person’s honour or reputation.

Our first reading: some reassurances, but incomplete. The parody and satire exceptions are welcome, and the court-ordered enforcement model is narrower than a duty to filter. But several points could affect Wikimedia projects:

  • A closed list of purposes. There is no explicit exception for news reporting, quotation, education, research, documentation or archiving. An encyclopaedic article about a notorious deepfake may need to show or link to it. That is a case where neither parody nor social criticism fits.
  • A balancing test. Even where an exception applies, it depends on a judge finding a “fair balance”. This creates a a lot of uncertainty, including for good-faith actors.
  • A broad definition. The definition requires neither intent to deceive, nor harm, nor absence of a label. “Manipulated by AI” could, depending on interpretation, reach AI-assisted restoration, colourisation or upscaling of historical photographs and footage. Protection also extends to deceased persons for 50 years.
  • Consent versus free licensing. Files on Wikimedia Commons are reused far beyond the Wikimedia projects. Will this new neighbouring right work with general public lincences?

The Danish Ministry of Culture’s bill amends the Copyright Act in two ways. A new section protects any person against the making available of realistic digitally generated imitations of their personal characteristics (appearance, voice) without consent. Another new section gives performing artists a similar protection against imitations of their performances. Protection would run for the person’s lifetime plus 50 years and applies in Denmark only. The exceptions cover caricature, satire, parody, pastiche, criticism of power, social criticism and similar uses.

The draft went to public consultation from 7 July to 21 August 2025 and was then notified to the Commission under the TRIS procedure (notification 2025/0654/DK, received 31 October 2025, a re-notification of a draft that had been withdrawn earlier). The planned entry into force was 31 March 2026. As far as we can tell, the bill has not been adopted and is stuck in the process.

The copyright route is deliberate: it lets victims use the notice-and-action mechanism of the DSA, and it would be tied into the Danish rule implementing Article 17 of the Copyright in the Digital Single Market (DSM) Directive.

Our reading: better drafted than the Belgian text, but not yet completely safe: The list of exceptions is broader (it includes pastiche and criticism of power), but our Danish chapter Wikimedia Denmark’s own conclusion was that the bill in its current form would limit the possibilities. The main concerns:

  • Informative, documentary and artistic use is not covered. WMDK points out that Commons holds realistic AI imitations of known people: artworks, satire or criticism of power, and “neutral” images used to illustrate articles on deepfakes and generative AI. Only the satire and criticism group clearly fits the exceptions, hence WMDK’s request to add imitations with a predominantly informative, educational or documentary purpose.
  • The exceptions turn on judgement calls. The exception is framed around imitations that are predominantly an expression of the listed purposes, with a further test of concrete risk of serious harm. In its own consultation response, the media association Danske Medier said these formulations require assessments that will be very difficult to make in practice.
  • Filtering pressure. The European Commission’s TRIS comments point to the risk of extended filtering duties.
  • Fragmentation. Commons projects are normally global in nature. How these special, national rules sit with a single, global repository is an open question.

Cyprus: A new sui generis right already law

In March 2026 the Cypriot House of Representatives adopted law amending its copyright rules. It creates a new sui generis right against imitations, through “deepfake products” (a term that cross-refers to Article 3(60) of the AI Act), of a person’s physical characteristics or of a performer’s performance. According to Tatiana Synodinou’s analysis on the Kluwer Copyright Blog, the text follows the Danish bill closely but is less elaborated, and it was enacted without public consultation or parliamentary debate.

  • Scope. The law prohibits making a deepfake imitation of a performer’s performance available to the public without express consent. To achieve this it gives every natural person a protection for their physical characteristics (morphology, voice, biometric and behavioural features), which lasts for 50 years after death.
  • Enforcement. The rules are those of copyright enforcement: civil action, damages and injunctions, plus criminal sanctions.
  • Exceptions. There is an exemption for satire and parody, caricature and political or social criticism. Both are overridden where the imitation amounts to “disinformation” that creates a “serious risk” to the rights or essential interests of others. No exception for informative, educational or documentary use.
  • Licensing. The amendments don’t say anything on whether the right can be licensed or transferred.

Our reading: problematic in several ways:
For Wikimedia, lack of exceptions for informative, educational or documentary use are problematic. Additionally, the “disinformation” and “serious risk” override makes even existing exceptions hard to predict. Another worry is that national sui generis rights can lead to fragmentation of law and the internet.

Do we need another layer?

Let’s take the most recent example. The Belgian memorandum argues that the existing framework is inadequate: the AI Act requires labelling but does not ban deepfakes, the GDPR protects only to a degree, and Belgian portrait and performers’ rights do not fit. These are fair observations. But the question we would put to every legislator is whether the gap is legal or practical. And what the goals are.

The current toolbox is already substantial and growing:

  • AI Act transparency rules on labelling deepfakes, and the agreed ban on AI “nudify” systems under the Digital Omnibus on AI;
  • DSA notice-and-action and risk-mitigation duties for platforms;
  • the GDPR, including erasure rights for personal data such as image and voice;
  • national personality, image and defamation laws, and criminal law on fraud and non-consensual intimate imagery, with EU rules requiring Member States to criminalise sexual deepfakes.

The worst harms (scams, sexual abuse imagery, election manipulation) are not primarily about someone’s lack of control over a commercial market in their likeness. Exclusive, licensable and inheritable rights, as in Belgium and Cyprus, create such a market and then require every legitimate use to fit an exception. A patchwork of 27 national regimes also sits poorly with a borderless internet and with the AI Act’s harmonised approach. The question remains, is the goal to protect people from abuse or is the goal to create a new market? Or both? The answer would inform the appropriate instrument and we should be honest about our intentions.

In any case, filling the potential gaps of currently existing instruments might be much more efficient. Whatever we do, we should at minimum:

  1. include open-ended public-interest exceptions for news, education, research, documentation and encyclopaedic use, quotation and archives, not only parody and satire;
  2. tie liability to deceptive or harmful use;
  3. keep intermediary obligations within the DSA liability regime;

World Space Week: deep-sky images from our community

Wednesday, 7 October 2026 12:00 UTC


Looking up for World Space Week (4-10 October)
, Ali Smith.

People have been looking up and telling stories about the night sky for as long as there have been people to look up! Communities have mapped their lives onto the stars: when to move camp, when animals would breed, when it was time to gather a particular food. The sky was a calendar, a map, and a library, all at once.

For World Space Week (4-10 October) —marking the anniversary of the first satellite launch—we are looking up to celebrate the many stories that make up astronomy across Australia and Aotearoa New Zealand. People are still going outside, still pointing to the sky, and still trying to capture what's up there to share the human story.

2025 Wiki Science Competition for Australia and New Zealand

We saw that instinct in the astronomy category of the 2025 Wiki Science Competition for Australia and New Zealand. These photographers have dedicated dozens of hours to bringing out the hidden, dusty spaces between the stars. We hope you enjoy them as much as we do!:

Deep image of the Angel Nebula (NGC 2170 and NGC 2182)

— regional winner, by Rolf Wahl Olsen. The Angel Nebula (NGC 2170 & NGC 2182) — Reflection and Emission Nebula in Monoceros "What attracted me most was the extraordinary colourful mixture of reflection nebulae, emission, and dark dust," says photographer Rolf Wahl Olsen, who spent over 33 hours imaging the region from their home observatory in Auckland using a self-built 12.5-inch telescope. "I particularly enjoy imaging these faint dusty regions because long integrations can reveal structures and colour that are invisible in shorter exposures."

The Angel Nebula (NGC 2170 & NGC 2182) — Reflection and Emission Nebula in Monoceros, by Rolf Wahl Olsen (Hwy37), CC BY-SA 4.0.

A deep two-panel mosaic of Messier 78 in Orion

— Messier 78 Behind Barnard’s Loop-  finalist, also by Olsen. Captured across nearly 40 hours of exposure, Olsen aimed to show the target not in isolation, but in context with the dark dust and gas surrounding it: "I wanted to show it not simply as an isolated dusty reflection nebula, but as part of the much larger dusty environment of the Orion Molecular Cloud."

Messier 78 Behind Barnard’s Loop by Rolf Wahl Olsen (Hwy37), CC BY-SA 4.0.

A newborn star city glowing in cosmic dust — finalist, by TheBrocketMan. "The HDR-style enhancement focused on bringing out the outer halo, faint filaments, and fine dust structure while preserving a realistic tone," shares TheBrocketMan, who used photo-stacking technology to reveal the delicate details hidden in the deep sky of the Orion Nebula.

The Orion Nebula, by TheBrocketMan, CC0

Community images

These images were captured by people in our own community, from their own backyards, and released under a free licence so anyone in the world can learn from them. Just as ancient skywatchers preserved knowledge through active community stewardship, open access to knowledge on Wikipedia relies on community custodians—volunteers who contribute, verify, and safeguard this shared library for everyone. Thank you to all our Wiki Science Competition contributors!

AI chat logs have timestamps

Wednesday, 7 October 2026 04:00 UTC

I believe at least half of my students are using AI inappropriately as of this fall 2026 semester. They are likely violating academic integrity policies and, more importantly, they are impairing their learning. As I wrote last summer, though, the biggest damage will be to the value and practice of honesty. Perhaps higher education will evolve, but in the meantime deceit is becoming common.

For those (demoralized) instructors attempting to hold the line—I’m lucky to have to do so for only one more year—I’ve learned something about AI chat logs. I don’t ban AI, but I require student work (understanding and prose) to be substantively their own. In short, “query, don’t copy & paste.” When students are confounded as to why their prose is flagged as AI, I sometimes ask them to share the thread, or students volunteer one, to help figure it out. I’ve now seen a few cases where students claim they can’t share a thread or offer a fabricated log as evidence that the work was their own. I’ve seen:

  1. Students fabricate a chat log and place it in a PDF or Word document. I respond by asking for the original.
  2. Students tell me the service they used doesn’t permit a thread to be shared. I respond that this is not true.
  3. After the fact, students create a new thread favorable to them, showing them asking for but rejecting the chatbot’s prose. I check the timestamps.

Yes, chatbots from the major services do have timestamps, though you might need to ask a chatbot to find the relevant attributes and convert the timestamps (from Unix epoch time).

Service Seen on the page Embedded in the HTML
ChatGPT None When the conversation began (the first 8 hex digits of backing_conversation_id are its epoch time) and each message’s epoch time, to the microsecond (create_time, though usually referenced by a number such as "_54" rather than by name)
Claude Each message’s date (e.g., “May 14, 2025”); the exact time likely shows on hover Each message’s exact time in UTC, to the millisecond, in a standard HTML tag (<time datetime="2025-05-14T18:53:34.287Z">)
Gemini When the thread was created and published (not each message), to the minute, in local time None

Episode 216: Christian Erlinger

Tuesday, 6 October 2026 19:26 UTC

🕑 1 hour 12 minutes

Christian Erlinger is a digital librarian and GLAM consultant; he is also the general chair for the MediaWiki Users and Developers Conference (MUDCon) Fall 2026, which will be held November 11-13, in Ljubljana, Slovenia.

Links for some of the topics discussed:

On September 2, more than 300 attendees joined the latest edition of Wiki Education’s Speaker Series, which returned to a subject it first explored in August 2025: Wikipedia in the age of generative AI. Moderated by Chief Programs Officer LiAnna Davis, the panel included Sage Ross, Wiki Education’s Chief Technology Officer and a longtime Wikipedia editor; Max Spero, CEO and co-founder of AI-detection company Pangram Labs; Oliver Wunsch, who teaches art history at Boston College; and Whitney Lew James, who teaches first-year writing at the University of Notre Dame.

AI erodes the signals editors rely on

Sage opened by identifying the most significant change to Wikipedia in the era of generative AI: an erosion of trust. Editors have traditionally assessed contributors by whether their writing is coherent and reflects familiarity with the subject.

“AI just does such a good job at making plausible text,” Sage said. “It really breaks down those signals that Wikipedia editors rely on to know how much trust to put in another person’s writing.”

AI also lowers the cost of manipulation, he added. Writing in Wikipedia’s neutral, encyclopedic tone once required real effort from those seeking to promote a person, product, or cause; AI removes that barrier and, as Sage noted, “lets you do things at a much higher scale.” Because chatbots incorporate new Wikipedia edits quickly, even obscure articles have become targets.

September 2026 Speaker Series group photo (resized for web)
Top (L-R): Whitney Lew James, Sage Ross. Bottom (L-R): Max Spero, Oliver Wunsch.

Verifiability is where AI breaks down

A consistent weakness surfaced across the panel: AI-generated text rarely corresponds to its citations. Sage explained that current models can produce accurate facts and suggest relevant sources, but linking a specific claim to a specific source “is where AI usually completely breaks down.”

Oliver has observed the same pattern in his courses.

“Without exception, [with] the text that has been flagged as AI generated through this Pangram integration, I’m always able to find some way in which the text fails the verifiability standard,” he said. He added that chatbots favor freely available online sources over authoritative books and paywalled scholarship.

Detection as a starting point, not a verdict

Max explained how Pangram’s classifier distinguishes human writing from AI-generated text. Sage described the evaluation that led Wiki Education to adopt the tool: running years of past student work through it. The results, he said, showed “zero hits from before late 2022 when ChatGPT launched.”

Even so, instructors treat a flag as the start of a conversation rather than a conclusion. Asked how she handles flagged work, Whitney said, “In short, I would say very carefully.” Some flags have traced back to AI-generated text already present in the Wikipedia articles her students were editing, which she uses to illustrate why the policy matters.

Lessons that reach beyond Wikipedia

Both instructors have found that discussions of AI enrich their broader curricula. Oliver’s students have drawn parallels between the arrival of AI and the invention of photography, and have examined what makes a painting such as Washington Crossing the Delaware appear trustworthy. The lesson, as he described it, is that an authoritative style is not evidence of accuracy: “You actually have to cross-reference with sources.”

For Whitney, the Wikipedia assignment conveyed the importance of citation more effectively than the traditional literature review it replaced, in part because students recognized how widely their work would circulate.

“This isn’t just writing an essay for me as your teacher,” she said.

A call to action

Asked to name one step instructors and editors can take to protect information integrity online, Whitney answered directly: “Contribute to Wikipedia.” Other panelists emphasized transparency about AI use, with Max cautioning that without proper disclosure, “we could enter this culture of much greater distrust.”

Join our next discussion

Wiki Education’s Speaker Series is a monthly, Zoom-based panel discussion that brings together experts in Wikipedia and open knowledge to examine topics relevant to our communities. Each session is moderated by a Wiki Education staff member, includes a live audience Q&A, and is recorded for Wiki Education’s YouTube channel.

The conversation continues this week! The October edition of the Speaker Series is free and open to anyone interested in Wikipedia, open knowledge, and the integrity of public information:

Communicating Science on Wikipedia
Thursday, October 8, 2026
1 pm Pacific / 4 pm Eastern
Zoom Registration


Learn more about teaching with Wikipedia at teach.wikiedu.org, or explore editing yourself at learn.wikiedu.org.

Recently, multiple organisations have disclosed how clusters of so-called “rogue” AI agents attempted to break into websites and online services, sometimes successfully. Agents from OpenAI’s environment, in particular, are known to have used other public wikis (collaboratively edited websites not owned by us) to communicate and coordinate with each other.

These types of successful intrusions can expose sensitive data or disrupt website services that users rely on, while clusters of agents can attempt attacks at a scale that is difficult for defenders to manage. They affect people behind the websites who may not understand the nature of the attack, or have the tools to effectively fight back. For a site like Wikipedia, agents might find and use security vulnerabilities or make misleading edits at scale. Wikipedia’s volunteer editors and the Wikimedia Foundation’s security teams have to detect and undo that activity.

The Wikimedia Foundation conducted its own investigation to see whether Wikimedia websites had been similarly affected by AI agents, focusing on those operated by OpenAI. We can confirm that we have discovered some activity by these “rogue” OpenAI agents on Wikimedia platforms. The unauthorized bot activities included edits to our wikis, some unsuccessful attempts to exploit a public note-taking tool we host, and heavy traffic, which are described more below.

We did not find any evidence that our systems were used for coordination among agents, nor did we find any evidence of our systems or data being compromised. However, we are concerned about what could have occurred here, the difficulty and effort involved in investigating and attributing this activity, and the growing risks of agentic AI activity on our platforms in general. The open web is a public good. We should not allow this behavior to become the “new normal” for the people or organizations that maintain it.

In summary, we saw:

  • Wiki editing: We’ve identified edits to Wikimedia wikis that we believe are from AI agents operated by OpenAI. These edits were not published to pages with visibility to general readers; almost all of them were testing edits in “sandbox” areas of the wiki. It also included a few edits to the configuration for a citation tool, which we believe were potentially malicious edits that were intended to misuse this tool as a proxy for fetching data from remote services. While Wikipedia policies allow bots to edit when they are disclosed and approved by the community, none of those approvals were sought in these incidents.
  • Etherpad probing and use: Agents we believe to be operated by OpenAI made some unsuccessful attempts to compromise our public Etherpad, a note-taking tool we host as a community service. Agents unsuccessfully tried to use it to fetch data from other websites as a proxy. Other agents also likely operated by OpenAI took notes about their tasks, though this did not appear to turn into coordination.
  • Excessive data downloading: Agents we believe to be operated by OpenAI made millions of automated requests to our public APIs to access the knowledge on Wikimedia projects, crawled millions of pages (mainly from our projects Wikidata and Wikimedia Commons), and made hundreds of thousands of data queries to the Wikidata Query Service (WQDS). This traffic may have contributed to a partial outage on WQDS in May.

As a non-profit technology host of some of the largest and most widely used open knowledge platforms in the world, we are deeply concerned about the impact of “rogue” AI agents on platforms like ours, which are built by volunteers from around the world and rely on the promise of the open internet. Incidents like this one, and the many others that have been (and are still being) uncovered, illustrate how AI agents can drain resources and crash servers, as well as attempt to compromise trustworthy information.

Over the past 25 years, Wikipedia has grown into one of the most popular and trusted websites in the world, with more than 67 million articles across over 300 languages, and up to 15 billion page views per month. Through an open, transparent, and collaborative process, volunteers work to ensure that knowledge remains neutral, reliable, and accessible to everyone. Wikipedia is one of the highest-quality datasets used in training Large Language Models (LLMs), and its knowledge forms the backbone of information on the internet, powering AI chatbots, search engines, voice assistants, and more.

Wikipedia was designed for humans – and agentic behavior clearly poses challenges that no one has solutions for. Because of our unique and successful knowledge creation model, Wikimedia’s volunteers are the ones who come in first contact with, and clean up the mess left behind by AI agents. Rising bot traffic and agentic activity is showing a real impact on the Wikimedia projects and the infrastructure that makes it available for millions of users globally. In 2025, the Foundation reported that its bandwidth usage had increased by 50% due to the surge of bot activity on its websites since 2024. At the same time, 65% of the most resource-consuming traffic on its projects was coming from bots.

This intense pressure on our infrastructure not only adds costs for servers and humans, but if left unaddressed, can block human visitors by overloading systems and causing outages. We are already paying for costs that come with the increased activity.

Wikimedia’s volunteers have stayed resilient so far in tackling emerging challenges on our platforms, but we also want to say: it doesn’t need to be this way.

While OpenAI admits to agents behaving “unpredictably”, they must also acknowledge their responsibility to monitor and prevent these risks. AI companies are not doing enough to secure their systems and protect the public from the harm they cause. That burden is falling onto everyone else, including smaller organizations. At a minimum, their systems should operate in a way that non-profit website owners like us can easily identify, and choose how they interact with our services.

The web enables so much: to connect with friends and family, to register for school, to plan a trip across town, to buy groceries, and to learn about the world from Wikipedia. Bots and agents are part of the future of the web, and the companies who unleash and profit from them must directly help avoid and repair damage they can do. 

Our collective priority should be the health of the overall web ecosystem so that it continues to benefit all people – not just a handful of billionaires. Wikimedia plays a critical role in stewarding the knowledge commons, but we cannot do it alone. We invite everyone who is building the future of the web to join us in protecting the open, shared resources that make that future possible.

The post OpenAI “rogue” agent activities found on Wikimedia projects appeared first on Wikimedia Foundation.

Wikipedia:Administrators' newsletter/2026/10

Monday, 5 October 2026 01:17 UTC

News and updates for administrators from the past month (September 2026).

Administrator changes

removed ·

Oversight changes

removed

Guideline and policy news

  • Following an RfC, the good article criteria have been amended to add accessibility requirements.
  • Following an RfC, late signatures added to administrator recall petitions after 720 hours from opening are reverted or struck and do not count towards the threshold, even if the petition has not yet been formally closed.
  • The post-May 2026 administrator elections RfCs concluded with consensus for election monitors to curate blatantly inappropriate questions after posting, and to remove or merge true duplicates, clearly marking merged questions. Calls for candidates will include advisory guidance that users with less than one year’s experience or 5,000 edits generally lack a realistic chance of success.

Technical news

  • Interface administrators no longer need to specify the ResourceLoader option in the definitions for gadgets on MediaWiki:Gadgets-definition as gadgets are always loaded through ResourceLoader. (T298199)
  • The list=abusefilters API module now supports formatversion=2 and includes breaking changes to its responses. In particular, the actions property is now a JSON array rather than a string, regardless of the format version. Maintainers of user scripts and other code using this module should check compatibility and update their code as needed. (T435828)

Arbitration

Obituaries

  • Doug Weller passed away on 30 September 2026. Doug Weller began editing Wikipedia in 2006 and became an administrator in 2008, making nearly 275,000 edits over two decades. He served on the Arbitration Committee from 2015 through 2018 and was also a longtime CheckUser and Oversighter.

Miscellaneous


Archives
2017: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2018: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2019: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2020: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2021: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2022: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2023: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2024: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2025: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11, 12
2026: 01, 02, 03, 04, 05, 06, 07, 08, 09, 10, 11
<<  Previous Archive    —    Current Archive    —    Next Archive  >>

weeklyOSM 845

Sunday, 4 October 2026 00:00 UTC
weeklyOSM 845
[1] World Ocean Floor - Manuscript painting of Heezen-Tharp ‘World Ocean Floor’ map by Berann. [?, 1977], Berann, Heinrich C, Bruce C Heezen, and Marie Tharp. Map. https://www.loc.gov/item/2010586277/. Reproduced by permission of Marie Tharp Maps, LLC 8 Edward St. Sparkill, NY 10976.

24/09/2026-30/09/2026

About us

  • We’re excited to announce that weeklyOSM is now accessible via news.osm.org, honouring the voices and contributions of our global community equally. The new domain redirects to weeklyOSM.eu.

Mapping campaigns

  • Eugene Alvin Villar announced the #31DayOSMChallenge proposed by the OpenStreetMap Foundation’s Local Chapters and Communities Working Group. See the Daily Challenges and note that you don’t have to contribute every day.

Community

  • Raquel Dezidério Souto wrote, in her OSM User Diary, that she has edited two new volumes of the book Case Studies in Collaborative and Participatory Mapping (one of which is a thematic dossier on risk and disaster reduction). She authored chapters on the application of OpenStreetMap in two case studies conducted in collaboration with the Brazilian Ministry of Integration and Regional Development (part of volume 2). In total, 35 chapters were published, and the two e-books are available as open access on the Editora IVIDES portal.

  • In Episode 284 of the Libre à Vous podcast, Anne L’Hôte presented a segment titled ‘complete your street’.

  • In a blog post Christoph Hormann reflected on the challenges of communication within open-source communities such as OpenStreetMap. He highlighted how language barriers, differing cultural backgrounds, and the peculiarities of digital text-based communication can lead to misunderstandings in discussions, and calls for greater understanding and thoughtfulness in these exchanges.

  • Reddit user u/Legitimate-Weight768 is currently mapping their hometown in Marcílio Dias, Canoinhas, Santa Catarina, Brazil, and is asking on Reddit for tips on how to improve their mapping skills with OSM.

  • The Wikimedia Ghana User Group has organised Wiki Loves Places 2026 in Ghana, aiming to collect at least 250 geotagged images of places, document 250 new place entities on Wikidata, and add or update 250 locations on OpenStreetMap.

  • A local category for Kalaallit Nunaat (Greenland) has been set up on the OSM Community forum.

  • 9_tab has written about Planet Trails in Switzerland. How many are there on OSM? How detailed is the mapping? What scale do they use? Do they include Pluto? What else? Which trails may be missing?

OpenStreetMap Foundation

  • Dorothea Kazazi announced that the OSMF board candidates’ manifestos and answers to the official questions, by Brian Sperlongano, are now available on the OSM Wiki.

  • Christoph Hormann discussed the upcoming OSMF board election 2026, saying that having four candidates for four seats makes the election ‘meaningless’ and could seriously damage the board’s legitimacy as a democratically elected representation of OSMF members.

Local chapter news

  • OpenStreetMap US has published its September 2026 newsletter.

  • InsertUser tooted that UK-based OSM mappers were able to vote for the next UK quarterly project until 28 September.

Events

  • The Centro Argentino de Cartografía (CAC) has posted a reminder on LinkedIn that the registration deadline for the 13th Congreso de la Ciencia Cartográfica, which is also the 4th Congreso Virtual Internacional, was 30 September 2026. The virtual congress will take place from 6 to 8 October 2026 and is being jointly organised by the CAC and the Argentine Instituto Geográfico Nacional.

  • Alpha Amadou Diallo reported that the municipality of Pire Goureye, Senegal hosted a collaborative mapping training activity with OpenStreetMap on 26 and 27 September 2026.

Education

  • Nelson Gonçalves published learning material introducing web mapping and uMap.

OSM research

  • Thiago Kikuchi and others have developed ► an interactive uMap showing the physical environment of urban river basins in Northern Paraná, Brazil, combining publicly available data on contour lines, slopes, soil types, hydrography, water bodies, springs, and watershed boundaries.

Maps

  • Mark Dimond used OSMnx to visualise which road in England carries the most buses.

  • Martin has developed a map that shows which konbini is closest to you in Tokyo and which chain dominates each area, using OpenStreetMap data.

  • NoEscapeMap has developed NoEscape 2.0, a web map that geocodes past cases of border-crossing attempts from Ukraine’s open court registry data, intended to help tourists and researchers analyse ► risks and avoid ► danger.

  • Stamen Design reported that their partner Stadia Maps has updated the underlying data used in several of Stamen’s basemaps, focusing on an overhaul of water features, such as rivers, lakes, and coastlines.

  • Map Amore showcased ‘The Arrogance of Space Mapping Tool’, a tool that shows how much space cars occupy in our cities.

  • Ogmios has built World Wide Waterways: Flussdiagram.me, a website where waterways are rendered in 1D maps with additional metadata from OpenStreetMap and Wikidata.

OSM in action

  • Sozialheld*innen has launched ► a11y-Score, a tool that makes accessibility in Germany visible and comparable through a score from 0 to 100 for federal states, 418 districts and independent cities, along with Germany as a whole, based on OpenStreetMap geodata.

  • BoxThisLap reported on TerraDrive, a new open-source map generator that converts OpenStreetMap and elevation data into driveable 3D environments. Released under the MIT licence, the tool utilises OSM’s road geometry, lane details, intersections, and building footprints to recreate real-world road networks, which can then be exported as playable levels for the vehicle simulation game BeamNG.drive.

  • Spino87 posted PizzaRank, a directory of 30,931 Italian pizzerias, a good 24,000 of which were sourced from OpenStreetMap, and also made the OSM portion available ► as a .CSV or .JSON file under the ODbL licence, as simple attribution is not sufficient for a derived database work. On the OSM Community forum he asked for advice on how to report any errors found in the process back to OSM; in discussions with Martin Koppenhöfer it emerged that the duplicates and incorrect municipality names were due to peculiarities of the osmium export tool or his own script, whilst the six pizzerias that have permanently closed should now be reported individually as notes. The data also revealed that the oven=wood_fired tag has hardly been used to date, which is why both suggested promoting it more actively via presets and a StreetComplete quest.

Open Data

  • After twenty years of service, IGN France is replacing ► Geoportail with its new portal designed as a single point of access to maps and territorial geographic data. The goal is to make the map an accessible, open, and useful digital tool both for everyday use and for major decisions, whether you’re simply curious, a hiker, a local elected official, or a professional. It contains maps from IGN and its partners, aerial photographs, and various maps (cadastral, forests, historical, topographic, and routes, etc).

  • Jake Low announced that Layercake, a distribution of OpenStreetMap data separated into thematic layers and converted into GeoParquet format, has a new website.

Software

  • Tykayn showcased Qualiwiki, a web dashboard to compare the content coverage between the English and French versions of the OSM Wiki.

  • The PapaMap shows the nearest changing table that parents can reach using OpenStreetMap data and is now available as an iPhone app, with an Android version currently in development.

  • Tobias Zwick announced the first public beta of StreetComplete for iOS.

Programming

  • HeiGIT introduced HeiSlime, a Python toolbox that uses OpenStreetMap context to select images useful for analysis before processing them with a computer vision model. The result is a smaller, more targeted image set that saves processing time.

  • The OSMF sysadmins tooted that upgrading to Mapnik 4.3.2 lead to significant performance improvements for raster tile rendering. On top of that, there are technical improvements to OSM Carto by leijuv and nakaner. Detailed explanations can be found on GitHub. Another, as yet unmerged, pull request to OSM Carto promises more performant sorting of features.

  • Sarah Hoffmann reported that Kai Johnson has improved the CPU usage metering per client on an Overpass server. The measurements are used to ban heavy users by IP address and/or application. She also noted that most of the bad traffic comes from poorly programmed speed camera apps.

  • In two Habr articles, Sunspirit described how his desire to create his own walking route led to the development of the route planner putemer.ru. In a follow-up technical article he explained why he switched from live Overpass API queries to his own OSM database, built from Geofabrik extracts and including a PMTiles map set, and uses elevation data, road network counts, plus cache settings, and how easily plausible measurements can lead to false conclusions.

Releases

  • Amanda McCann recently added several new features to WaterwayMap, including multilingual names and integration with Wikidata and Wikipedia.

  • Michael Johnson released NodeODM 3.6.2 to match the latest OpenDroneMap 3.6.2 release.

Other “geo” things

  • [1] The Woods Hole Oceanographic Institution reported that Marie Tharp was inducted into the National Women’s Hall of Fame in 2026. Using thousands of sonar readings from research vessels, Tharp and Bruce Heezen revealed a 40,000-mile underwater ridge girdling the globe, helping confirm plate tectonics and continental drift theory, which were controversial among geologists at the time. This work led Tharp to create the World Ocean Floor Map, published in 1977 by the Office of Naval Research and still widely used today. The Columbia Climate School has made an interactive guide to the ‘Heezen–Tharp World Ocean Floor Map’.

  • Researchers at Tufts University, led by Farshid Vahedifard, have analysed more than 190 million satellite and ground measurement points along the US coastline and found that 71.5% of the areas are sinking by more than one millimetre per year. The Gulf Coast is sinking the most, with 92.6% of measurement points showing downward movement at a median rate of 2.5 millimetres per year. The study also overlaid the subsidence map with population and infrastructure data and found a disproportionate impact on disadvantaged communities.

  • NATO is seeking to procure a global vector basemap compliant with STANAG 2592 NGIF to support web mapping, rapid mapping, geospatial analysis, routing, and geolocation services. The package will centre on vector data combining current Overture Maps data with vendor-furnished data and other open or purchaser-provided sources, alongside derived products such as raster and vector caches, routable networks, and geolocator files. The procurement has an estimated value of EUR 3.5 million and is expected to be awarded in February 2027.

  • A Lithuanian musician and self-styled ‘mythographer’ has renamed ► a striking rock formation at the Predigtstuhl, near Bad Reichenhall, on Google Maps from ‘Teufelssattel’ to ‘Wächter der Alaunen’ (after an ancient Celtic tribe that fascinates him) whereas the historical name is documented as early as 1580 by Philipp Apian. The local historical society, led by town archivist Johannes Lang, subsequently contacted Google, as the responsible Bavarian surveying authority had omitted the name from its map solely for graphical reasons, but had not replaced it. It was only with the technical support of a computer scientist that the old name was successfully restored. Lang sees this as an example of the growing trend towards ’emotional historiography’. The BR Quer programme also reported this at 00:39.

  • MapTheNet displays a map of websites. Domains are placed near other domains they are linked to, and scaled according to the number of weighted incoming links. You can search a domain and see how it is connected to others, for example weeklyosm.eu.

Upcoming Events

Country Where Venue What When
🇮🇳 Kottayam Mapathon Pre-event SotM Kerala 2026 2026-10-01 - 2026-10-05
🇮🇹 Messina Fablab Messina (via Croce Rossa 63, 98124 Messina) Hackathon Wikimedia & OSM 2026-10-02 - 2026-10-04
🇩🇪 Essen Linuxhotel Essen FOSSGIS-OSM-Communitytreffen Nr. 26 im Linuxhotel 2026-10-02 - 2026-10-04
🇪🇸 Langreo Casa de la Cultura “Escuelas Dorado” GeoCamp 2026 2026-10-03
🇫🇷 Mairie de Laillé OSM Mapping 2026-10-03
🇮🇳 नई दिल्ली Jitsi Meet (online) OSM India - Monthly Online Mapathon 2026-10-03
🇩🇪 Essen Verkehrs- und Umweltzentrum Essen OSM-Treffen 2026-10-03
🇮🇳 Chennai Corporation Velachery, Chennai Chennai GLUG Velachery OSM Mapping 2026-10-04
TNEI Mapathon 2026 2026-10-05
🇹🇼 臺北市 MozSpace Taipei OpenStreetMap x Wikidata Taipei #93 2026-10-05
🇨🇭 Bern SBB Headquarter Open Transport Community Conference 2026 2026-10-06 - 2026-10-09
🇬🇧 Sheffield Rutland Arms OSM Sheffield - Monthly Social 2026-10-06
🇪🇸 Madrid Online Mappy Hour OSM España 2026-10-06
🇦🇹 Salzburg Bewohnerservice Elisabeth-Vorstadt OSM-Treffpunkt 2026-10-06
🇩🇪 Braunschweig Stratum 0 Braunschweiger Mappertreffen im Stratum 0 Hackerspace 2026-10-06
Missing Maps London Mapathon Beginner Friendly (with Training) (Online) [eng] 2026-10-06
iD Community Chat 2026-10-07
🇬🇭 Ghana Everywhere She Maps workshop 2026 2026-10-07 - 2026-10-08
🇮🇹 Milano Building 4, SRN 4.1.1 Politecnico di Milano PoliMappers Maptedì 2026-10-07
🇸🇰 Žilina Fakulta riadenia a informatiky UNIZA Missing Maps mapathon Žilina #24 2026-10-07
🇧🇪 Liège Barricade, Liège Carto party OpenStreetMap Café Crypté Liège 2026-10-07
🇪🇸 Barcelona Barcelona Junta d’OpenStreetMap Català 2026-10-07
🇩🇪 Stuttgart Forum 3 Café Stuttgarter OpenStreetMap-Treffen 2026-10-07
th กรุงเทพมหานคร Brighton College Bangkok Mapathon Missing Maps Mapathon (Beginner) - Bangkok, Thailand 2026-10-08
🇧🇪 Bruxelles - Brussel Galerie Bortier Brussels meetup - byebye Thierry & Joost 2026-10-08
🇩🇪 Bochum Das Labor, Alleestraße 50, Bochum OSM-Treffen Bochum 2026-10-08
🇩🇪 Berlin Grosse Hamburger Strasse 37, 10115 Berlin 220. OSM-Stammtisch Berlin-Brandenburg 2026-10-09
🇨🇭 Bern irgendwo im Breitsch, wird noch definiert OSM-Znacht in Bern 2026-10-09
🇮🇹 Catania Biblioteche Riunite Civica e A. Ursino Recupero Modifichiamo Wiki e OSM insieme! - Catania 2026-10-10
🇫🇷 Angers École Nationale Supérieure d’Arts et Métiers OpenStreetMap, des cartes à la carte ! 2026-10-10
🇩🇰 København Cafe Bevar’s OSMmapperCPH 2026-10-11
🇫🇷 Angers École Nationale Supérieure d’Arts et Métiers OpenStreetMap, des cartes à la carte ! 2026-10-11
🇮🇳 New Delhi East Delhi OSM Delhi Mapping Party No.33 (East Zone) 2026-10-11
Panoramax Nederland - Online Community Meeting #1 2026-10-12
CartONG : Mapathons en ligne 2026-2027 2026-10-12
🇳🇱 Amsterdam TomTom HQ 2026 Autumn Maptime 2026-10-12
🇩🇪 München Echardinger Einkehr Münchner OSM-Treffen 2026-10-13
🇩🇪 Hamburg Voraussichtlich: “Variable”, Karolinenstraße 23 Hamburger Mappertreffen 2026-10-13
🇩🇪 temporärhaus OSM-Stammtisch Ulm/Neu-Ulm 2026-10-13
🇬🇧 Canolfan Cefnfaes 🏴󠁧󠁢󠁷󠁬󠁳󠁿 North Wales Mapathon Gogledd Cymru 🏴󠁧󠁢󠁷󠁬󠁳󠁿 2026-10-14
🇪🇸 Barcelona Barcelona Assemblea d’OpenStreetMap Català 2026-10-14
🇧🇪 Bruxelles - Brussel Tour & Taxis, Avenue du Port 86C - 1000 Brussels FOSS4G Belgium 2026-10-15
OSMF Engineering Working Group meeting 2026-10-16
🇦🇷 Pergamino Hub de Innovación Encuentro OSM Argentina 2026 2026-10-17
🇫🇷 Metz Espace Arob@se - Metz Atelier OpenStreetMap Metz 2026-10-17

This weeklyOSM was produced by MatthiasMatthias, Nakaner, PierZen, Raquel Dezidério Souto, Strubbl, Andrew Davidson, barefootstache, derFred.
We welcome link suggestions for the next issue via this form and look forward to your contributions.